
Zum Inhalt springen
Alpha
  • Modelle
  • Ranglisten
  • Ori
Vertrieb kontaktieren

Fußzeile

OpenRouterOpenRouter
© 2026 OpenRouter, Inc

Produkt

  • Chat
  • Ranglisten
  • Leistungsvergleiche
  • Apps
  • Entdecken
  • Modelle
  • Ori
  • Sammlungen
  • Anbieter
  • Tools
  • Preise
  • Business
  • Enterprise
  • Labs

Unternehmen

  • Über
  • Blog
  • Kunden
  • Karriere
    Offene Stellen
  • Datenschutz
  • Nutzungsbedingungen
  • Vertrauenszentrum
  • Support
  • Funktioniert mit OR
  • Daten
  • Marke

Entwickler

  • Dokumentation
  • API-Referenz
  • Entwicklerplattform
  • Status
  • KI-Sitemap

Verbinden

  • Discord
  • GitHub
  • LinkedIn
  • X
  • YouTube
Favicon für qwen

Qwen: Qwen Image 3 Pro

qwen/qwen-image-3-pro

LeistungsvergleicheVergleich

Qwen Image 3 Pro is an image generation and editing model from Qwen. It supports precise rendering of text and details as small as 10px, along with richer world knowledge compared to previous generations.

Modalitäten
Preis
from 0,04 $/image
Kontext
66K
Veröffentlicht
5. Aug. 2026
LeistungsvergleicheVergleich
TestumgebungLeistungsvergleicheAnbieterPreiseLeistungVerfügbarkeitAppsAktivitätFAQEntdecken

Example outputs summary for Qwen: Qwen Image 3 Pro

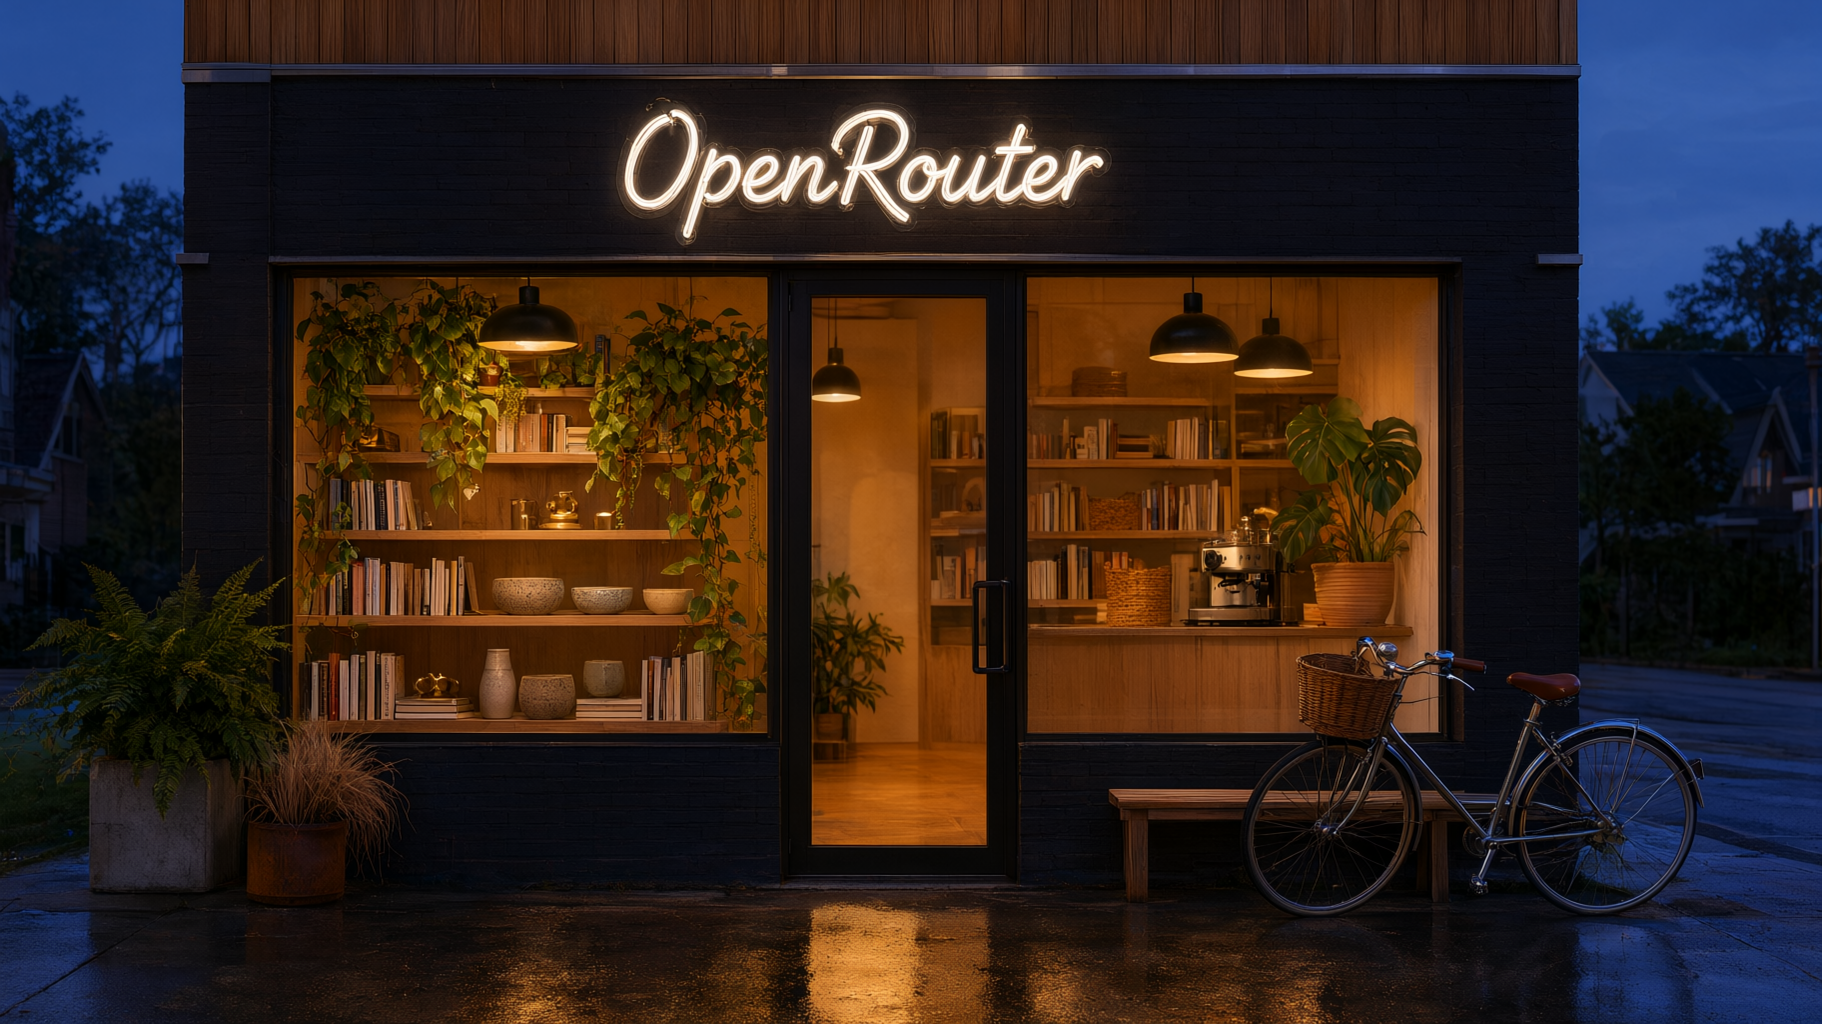
  • Text zu Bild: Editorial architectural photograph of a contemporary neighborhood storefront at blue hour, glowing warmly against the dusk. Above the entrance, a warm-white neon sign in flowing hand-bent cursive reads exactly "OpenRouter", the only text in the scene. Large windows reveal a cozy, lived-in interior: wood shelves styled with books and ceramics, lush trailing plants, and soft pendant lighting. Potted plants and a bicycle rest by the entrance, and golden light spills across the wet pavement in gentle reflections. Straight-on composition, realistic materials, quiet street with no people. — generiert mit Qwen: Qwen Image 3 Pro

Testumgebung

Leistungsvergleiche

Ergebnisse standardisierter Bewertungen und eigene Ausgaben dieses Modells zu gemeinsamen Vergleichstest-Prompts. Höhere Prozentwerte sind besser – und jeder Rang zeigt, wo dieses Modell unter den anhand dieser Quelle bewerteten Modellen liegt.

Benchmark outputs summary for Qwen: Qwen Image 3 Pro

  • Full wine glass: A wine glass filled to the brim with white wine, the surface level with the rim of the glass, standing upright on a plain wooden table. Straight-on eye-level shot, glass upright and not tilted, no other objects in the frame. (Geteilter Platz 10. von 60 bei diesem Prompt)
  • Closed umbrellas: Wide street-level photograph of about twelve people crossing a city street in heavy rain. Every person is carrying a closed, furled umbrella held down at their side. Not a single umbrella is open. Each umbrella is clearly visible. They are all getting soaked. No other people in the frame. (Geteilter Platz 1. von 60 bei diesem Prompt)
  • Three fingers: Close straight-on photograph of an open right hand raised palm towards the camera, with exactly three fingers extended straight up and the other two folded down into the palm. Plain background, nothing else in the frame. (Geteilter Platz 1. von 60 bei diesem Prompt)
  • Cards & dice: Exactly four playing cards face up in a single straight row on a polished marble counter, evenly spaced, all the same size, showing the seven of hearts, the eight of spades, the nine of diamonds and the ten of clubs from left to right. No other objects in the frame. Straight-on eye-level shot, soft even light. (Geteilter Platz 1. von 60 bei diesem Prompt)
  • Long exact string: A white A4 poster on a brick wall reading exactly "SPRING CLEARANCE - EVERYTHING 40% OFF - SATURDAY 14 JUNE, 9AM TO 6PM". No other text in the frame. (Geteilter Platz 29. von 60 bei diesem Prompt)
  • Multiple languages: Straight-on photograph of a white overhead directional sign in an international airport terminal, with a black arrow pointing right at the left end. The sign carries the same word in four scripts on four stacked lines, in this order from top to bottom: "DEPARTURES", then the Japanese 出発, then the Korean 출발, then the Arabic المغادرة. Clean sans-serif lettering, sharp focus, no other text anywhere in the frame. (Geteilter Platz 1. von 60 bei diesem Prompt)
  • Occlusion: Straight-on eye-level photograph of a plain wooden desk. On the left, a closed hardcover book with a dark red cover stands upright, its front cover facing the camera. A blue ceramic mug stands on the desk to the right of the book and clearly further back, about 20 cm behind it, positioned so that the right edge of the book overlaps and hides the left third of the mug. The mug's handle points to the right and the whole rim of the mug is visible. Bare desk surface is visible between the book and the mug. Nothing else on the desk. Plain wall behind, soft even light. (Geteilter Platz 1. von 60 bei diesem Prompt)
  • Mirror: Straight-on eye-level photograph of a bathroom vanity. A large rectangular mirror covers the wall behind the counter and its bottom edge meets the countertop, so both the objects and their reflections are visible. On the counter, a tall red toothbrush cup on the left and a tall green glass bottle on the right, both roughly 20 cm tall and well apart from each other. The mirror reflects the counter and the objects on it accurately. Nothing else in the frame. (Geteilter Platz 2. von 60 bei diesem Prompt)
  • Plain zebra: Photograph of a zebra standing side-on in short grass. Its coat is a uniform solid grey with no stripes, no bands and no markings of any kind anywhere on its body. The whole animal is visible. Sharp focus. (Geteilter Platz 1. von 60 bei diesem Prompt)
  • Times Square: Wide street-level photograph of Times Square in New York at night, wet asphalt reflecting the lights. Every billboard, screen, storefront window, awning, taxi door and road marking is completely blank — lit with plain colour fields and soft gradients only. No letters, no words, no numbers, no logos, no lettering of any kind anywhere in the frame. Sharp focus, straight-on shot. (Geteilter Platz 1. von 60 bei diesem Prompt)
  • Minimal diff: From the reference photo, change only the sign text to "ROUTE 7 ESPRESSO - OPEN TILL 8". Keep the sign, wall, lighting and framing identical. (Geteilter Platz 5. von 60 bei diesem Prompt)
  • Object removal: Remove only the second cup from the left in the reference photo. Leave the other four cups exactly as they are, in the same positions, and leave the shelf, towel, wall, plant and lighting untouched. (Geteilter Platz 23. von 60 bei diesem Prompt)
  • Person removal: In the reference photo, remove only the person in the yellow coat. Their shadow on the pavement and their reflection in the shop window must be removed as well. Reconstruct the pavement and the window glass behind them. The person in the red coat and the person in the green coat must stay completely unchanged, including their own shadows and their own reflections. Change nothing else in the frame. (Geteilter Platz 1. von 60 bei diesem Prompt)
  • Product placement: Product photograph of the ceramic mug from the reference image, standing upright on a café table. Show the same side of the mug, from the same side-on eye-level angle as the reference, with the handle on the right. The shape, proportions, colours, moulded relief and every painted detail must match the reference exactly. Only the setting and lighting change: soft daylight in a café interior, shallow depth of field. (Geteilter Platz 36. von 60 bei diesem Prompt)
  • Portraits: Studio headshot of a woman in a charcoal blazer against a mid-grey seamless backdrop, lit by a large softbox slightly above and to the left with a soft fill from the right, catchlights in both eyes. An 85mm look with shallow depth of field, skin texture and flyaway hairs kept rather than smoothed.
  • People in scenes: Photograph of four cooks working the pass in a restaurant kitchen at service, plating three dishes at once, several hands in frame and some of them overlapping. One cook partly hidden behind another, steam rising into hard overhead light, each face clearly a different person.
  • Animals: Photograph of a tabby cat asleep on a sunlit windowsill, fur lit from behind so the individual hairs glow at the edges, one ear turned toward the camera. Shallow depth of field, a houseplant soft in the background, quiet morning light.
  • Landscape and nature: Photograph of an old-growth temperate rainforest after rain, moss on every trunk and fallen log, ferns dense across the floor, thin fog between the far trees. Overcast light with no direct sun, everything from the nearest fern to the last trunk in focus.

Anbieter

Dieses Modell wird von einem einzigen Anbieter gehostet. OpenRouter leitet jede Anfrage direkt an ihn weiter – es sind keine Routing-Entscheidungen erforderlich.

Preise

Der durchschnittliche Preis, den Kunden tatsächlich für dieses Modell zahlen, neben den von Anbietern veröffentlichten Preisen. Durch Caching und Rabatte liegt der tatsächlich gezahlte Preis oft deutlich unter dem Listenpreis.

Leistung

Der Durchsatz gibt an, wie schnell das Modell schreibt (Token pro Sekunde – höher ist besser). Die Latenz ist die gesamte Umlaufzeit (niedriger ist besser). TTFT ist die Zeit bis zum ersten Token – also die Wartezeit, bis etwas angezeigt wird (niedriger ist besser).

Verfügbarkeit

Verfügbarkeit ist der prozentuale Anteil der letzten 3 Tage, in dem mindestens ein Anbieter auf Anfragen reagiert hat. Die Verfügbarkeit der Inferenz ist der prozentuale Anteil der Zeit, in der Inferenz erfolgreich bereitgestellt wurde. OpenRouter überwacht dies kontinuierlich und verwendet den nächstbesten Anbieter, wenn ein Anbieter einen Fehler zurückgibt.

Apps

Öffentliche Apps, die den meisten Datenverkehr an dieses Modell senden. Ein guter Anhaltspunkt dafür, wie echte Produktionsworkloads aussehen – und ein Hinweis darauf, für welche Anwendungsfälle dieses Modell am besten geeignet ist.

Aktivität

Token-Volumen und Anfrageaufkommen für dieses Modell im Zeitverlauf.

API

Direkt einsetzbarer Code zum Aufrufen dieses Modells. Die API von OpenRouter ist OpenAI-kompatibel – bei den meisten SDKs genügt es, die Basis-URL auszutauschen. Zwischen den Modellen ändert sich nur der unten stehende Modell-Slug.

Derzeit nicht über EU-regionales Routing verfügbar. Dokumentation zum regionsinternen Routing

Weitere Modelle entdecken

KI-Modelle mit Bildverarbeitung: Multimodale LLMs für das BildverständnisSammlungModelle zur BildgenerierungSammlungModellranglisten für BildmodelleRangliste
Ende-zu-Ende-Latenz
0,003 $0,04 $63,36s
100,00 %
Ende-zu-Ende-Latenz
63,36s

P50, bester Anbieter

Verfügbarkeit (3 Tage)Das Modell war erreichbar. Die Anfrage wurde an einen Anbieter weitergeleitet.
99,96 %
Verfügbarkeit (3 Tage)Das Modell hat über einen beliebigen Anbieter ein Inferenzergebnis zurückgegeben. Fehler und leere Antworten wirken sich negativ darauf aus.
97,78 %

Verfügbarkeit in den letzten 3 Tagen

Letzte 72 Stunden
Verfügbarkeit 97,78 %
Vor 3 TagenVor 2 TagenGesternJetzt

Verfügbarkeit in den letzten 24 Stunden

OpenRouter Availability
98,62 %

Wenn bei einem vorgelagerten Anbieter ein Fehler auftritt, können wir diesen durch die Weiterleitung an einen anderen funktionsfähigen Anbieter beheben, sofern Ihre Anfragefilter dies zulassen. Sie können programmgesteuert auf die Verfügbarkeitsdaten pro Anbieter zugreifen, und zwar über die Endpunkt-API. Erfahren Sie mehr über unsere Optionen für Lastverteilung und Anbieter-Routing.

1.
Favicon für https://stellaria.local/
Stellaria SuperResolution
neu
3,7MToken
2.
Favicon für https://gwgwgroup.com/
GWGW Wisdom Spring
neu
2,42MToken
3.
Favicon für https://gab.ai/
Gab AI
neu
1,7MToken
4.
Favicon für https://minaki.shop/
Minaki Collection Page Pod
neu
948KToken
5.
Favicon für https://cherry-ai.com/
Cherry Studio
neu
863KToken

Häufig gestellte Fragen

Qwen Image 3 Pro is an image generation and editing model from Qwen. It supports precise rendering of text and details as small as 10px, along with richer world knowledge compared to previous generations.

Qwen Image 3 Pro kostet von 0,04 $/image bei 1K bis 0,075 $/image bei 2K für Image Output und 0,003 $/image für Image Input.

Qwen Image 3 Pro rendert in 1K und 2K, unterstützt die Seitenverhältnisse 1:1, 1:2, 1:4, 2:1, 2:3, 3:2 und 7 weitere und kann bis zu 6 Bilder pro Anfrage generieren.

Qwen Image 3 Pro akzeptiert Text und Bilder als Eingabe und gibt Bilder zurück. Einer Anfrage zur Bildbearbeitung können bis zu 3 Referenzbilder angehängt werden.

Qwen Image 2.1 Turbo, Qwen Image 2.1 Pro und Qwen Image 3 sind weitere Modelle von Qwen für die Modalität Bild.

Qwen Image 3 Pro wurde am 5. August 2026 veröffentlicht.

Weitere Modelle von Qwen

Qwen Image 2.1 Turbo

Qwen Image 2.1 Turbo is the fast, lower-cost tier of the Qwen Image 2.1 series from Qwen, for image generation and editing where throughput and price matter more than peak fidelity. See Qwen Image 2.1 Pro for the higher-quality tier.

Bildfrom 0,0184 $/image
Qwen Image 2.1 Pro

Qwen Image 2.1 Pro is an image generation and editing model from Qwen, the higher-quality tier of the Qwen Image 2.1 series. Choose it over Qwen Image 2.1 Turbo when output fidelity matters more than cost or speed.

Bildfrom 0,046 $/image
Qwen3.8 Max Prime

Qwen3.8 Max Prime is a higher-throughput variant of Qwen3.8 Max from Alibaba's Qwen team, served as a separate SKU at a higher price point. It accepts text, image, and video input and returns text, with a 1M-token context window and reasoning enabled by default. Tool calling, structured outputs, and configurable reasoning effort are supported, matching Qwen3.8 Max.

Text1M Kontext4 $ / 12 $
Qwen3.8 Omni Flash

Qwen3.8 Omni Flash is an omni-modal reasoning model from Alibaba, the first Qwen model built around agentic capabilities with native audio-video understanding. It is suited for audio-video analysis and summarization, video editing and production workflows, audio-video dialogue, coding, knowledge work, and GUI interaction, and it is particularly strong at long-form multimedia tasks that combine speech, sound, and visual context. It also supports two-channel and four-channel spatial audio understanding.

Text1M Kontext0,15 $ / 0,47 $
Qwen3.8 Max

Qwen3.8 Max 0902 is an updated snapshot of Qwen3.8 Max from Alibaba's Qwen team. It is a 2.4-trillion-parameter mixture-of-experts model that accepts text, image, and video input and returns text, with a 1M-token context window and reasoning enabled by default.

This snapshot is post-trained for coding and agentic work, including multi-step software projects, multi-tool orchestration, and long-horizon task execution. It also targets chart reasoning, document parsing, and multimodal understanding over long documents and extended video. Tool calling, structured outputs, and configurable reasoning effort are supported.

Text1M Kontext2 $ / 6 $
Qwen3.8 Flash

Qwen3.8 Flash is a multimodal reasoning model from Alibaba. It is suited for coding assistance, agentic workflows, visual understanding, document and codebase analysis, desktop interaction, chart analysis, and long-video analysis.

Text1M Kontext0,15 $ / 0,47 $
Qwen3 Reranker 0.6B

Qwen3 Reranker 0.6B is the smallest text reranking model from Alibaba Cloud in the Qwen3 Reranker series. Built on the Qwen3 architecture, it evaluates query-document pairs to produce relevance scores for retrieval and RAG pipelines. Supports 100+ languages with instruction-aware reranking. Designed for low-latency, resource-constrained deployments.

Neubewertung
Qwen3 Reranker 4B

Qwen3 Reranker 4B is a text reranking model from Alibaba Cloud built on the Qwen3 architecture. It evaluates query-document pairs to produce relevance scores for use in retrieval and RAG pipelines. Supports 100+ languages and programming languages, with instruction-aware reranking that allows customizing scoring criteria per task. A compact 4B alternative balancing performance and inference cost.

Neubewertung
Qwen3.8 27B

Qwen3.8 27B is an open-weight dense vision-language model from Qwen. It is suited for coding, professional workflows, research, multimodal interaction, and long-running agent tasks, with flexible thinking that can be enabled or disabled.

Text1,0M Kontext0,004 $ / 0,231 $
Qwen3 Reranker 8B

Qwen3 Reranker 8B is a text reranking model from Alibaba Cloud built on the Qwen3 architecture. It evaluates query-document pairs to produce relevance scores for use in retrieval and RAG pipelines. Supports 100+ languages and programming languages, with instruction-aware reranking that allows customizing scoring criteria per task. Offers strong performance on multilingual benchmarks including MTEB, CMTEB, and MMTEB.

Neubewertung0,20 $/M tokens
Qwen3 ASR 1.7B

Qwen3 ASR 1.7B is an automatic speech recognition model from Qwen. It supports multilingual language identification and transcription across 30 languages and 22 Chinese dialects, with streaming and offline inference plus segment-level and word-level timestamps.

Transkription0,000008 $/second
Qwen3 ASR 0.6B

Qwen3 ASR 0.6B is a compact automatic speech recognition model from Qwen. It supports multilingual language identification and transcription across 30 languages and 22 Chinese dialects, with streaming and offline inference plus segment-level and word-level timestamps.

Transkription0,000003 $/second
Qwen3.8 2.4T A95B

Qwen3.8 2.4T A95B is an open-weight sparse mixture-of-experts model from Qwen and the open-weight variant of Qwen3.8 Max, with 95 billion active parameters out of 2.4 trillion total. It is suited for coding, research, complex reasoning, and agentic workflows.

Text1,0M Kontext2 $ / 6 $
Qwen Image 3

Qwen Image 3 is a unified image generation and editing model from Qwen. It supports precise rendering of text and details as small as 10px, along with a richer world knowledge base than previous generations.

Bildfrom 0,03 $/image
Qwen3.8 Max

Qwen3.8 Max (0803) is the August 3, 2026 checkpoint of Qwen3.8 Max, the flagship model in Alibaba's Qwen3.8 series and the general-availability successor to the Qwen3.8 Max Preview. It is a multimodal reasoning model intended for complex reasoning, visual understanding, coding, and agentic workflows. This checkpoint was superseded by Qwen3.8 Max (0902) on September 5, 2026.

Text1M Kontext
Qwen3.7 Flash

Qwen3.7 Flash is a vision-language reasoning model from Alibaba. It is suited for multimodal agents, visual coding, search, and computer interaction, with strengths in object recognition, spatial understanding, and real-world visual perception.

Text1M Kontext0,03 $ / 0,13 $
Qwen-Audio-3.0-TTS Flash

Qwen-Audio-3.0-TTS Flash is Alibaba's fast, cost-efficient text-to-speech model, generating spoken audio from text via the DashScope Speech Synthesizer API.

Sprache15 $/M characters
Qwen-Audio-3.0-TTS Plus

Qwen-Audio-3.0-TTS Plus is Alibaba's higher-quality text-to-speech model, generating spoken audio from text via the DashScope Speech Synthesizer API.

Sprache20 $/M characters
Qwen3.7 Plus

Qwen3.7-Plus is a cost-effective model in Alibaba's Qwen3.7 series. It supports text and image input with text output, building on the series' text capabilities with a comprehensive upgrade to its vision-language abilities while retaining full-stack, agent-level intelligence for coding, tool use, and productivity workflows. Its distinguishing trait is multi-modal interactive hybrid agent capability: it can perceive real-world scenes, read screens and interact with GUIs, generate code from visual references, and perform end-to-end navigation within mobile apps.

Text1M Kontext0,32 $ / 1,28 $
Qwen3.7 Plus (batch)

Qwen3.7-Plus is a cost-effective model in Alibaba's Qwen3.7 series. It supports text and image input with text output, building on the series' text capabilities with a comprehensive upgrade to its vision-language abilities while retaining full-stack, agent-level intelligence for coding, tool use, and productivity workflows. Its distinguishing trait is multi-modal interactive hybrid agent capability: it can perceive real-world scenes, read screens and interact with GUIs, generate code from visual references, and perform end-to-end navigation within mobile apps.

Text262K Kontext0,23 $ / 0,92 $