Saltar al contenido
Alfa
  • Modelos
  • Clasificaciones
  • Ori
Hablar con ventas

Pie de página

OpenRouterOpenRouter
© 2026 OpenRouter, Inc

Producto

  • Chat
  • Clasificaciones
  • Pruebas de rendimiento
  • Aplicaciones
  • Descubrir
  • Modelos
  • Ori
  • Colecciones
  • Proveedores
  • Herramientas
  • Precios
  • Business
  • Enterprise
  • Laboratorio

Empresa

  • Acerca de
  • Blog
  • Clientes
  • Empleo
    Empleo
  • Privacidad
  • Términos del servicio
  • Centro de confianza
  • Soporte
  • Compatible con OR
  • Datos
  • Marca

Desarrollador

  • Documentación
  • Referencia de la API
  • Plataforma para desarrolladores
  • Estado
  • Mapa del sitio para IA

Conectar

  • Discord
  • GitHub
  • LinkedIn
  • X
  • YouTube
Favicon de microsoft

Microsoft AI: MAI-Image-2.5

microsoft/mai-image-2.5

Pruebas de rendimientoComparar

Microsoft AI's MAI-Image-2.5 is a high-quality image generation model available via Azure AI Foundry. It produces photorealistic and artistic images from text prompts with support for various aspect ratios.

Modalidades
Precio de entrada / salida
8 US$ / 47 US$por 1M
Contexto
4K
Publicado
2 jun 2026
Pruebas de rendimientoComparar
Zona de pruebasPruebas de rendimientoProveedoresPreciosRendimientoTiempo de actividadAplicacionesActividadPreguntas frecuentesExplorar

Example outputs summary for Microsoft AI: MAI-Image-2.5

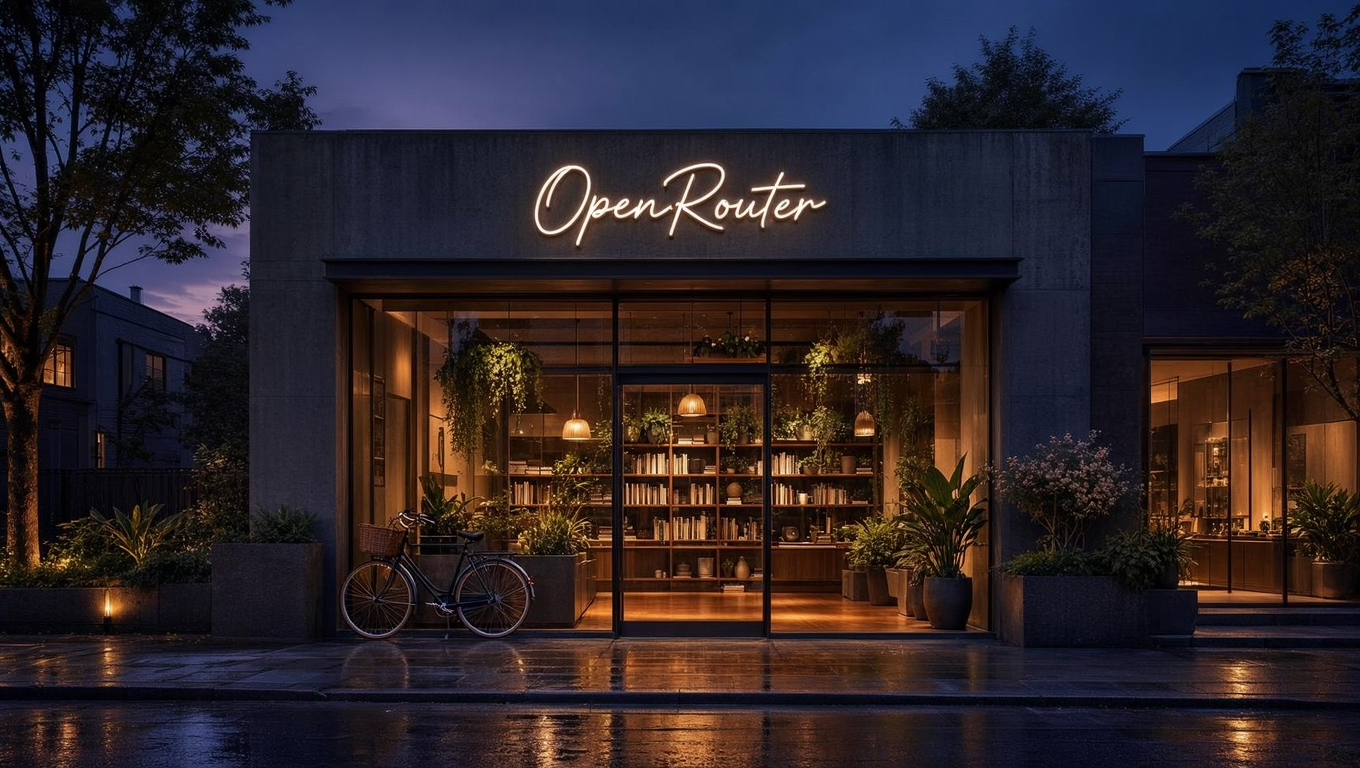
  • Texto a imagen: Editorial architectural photograph of a contemporary neighborhood storefront at blue hour, glowing warmly against the dusk. Above the entrance, a warm-white neon sign in flowing hand-bent cursive reads exactly "OpenRouter", the only text in the scene. Large windows reveal a cozy, lived-in interior: wood shelves styled with books and ceramics, lush trailing plants, and soft pendant lighting. Potted plants and a bicycle rest by the entrance, and golden light spills across the wet pavement in gentle reflections. Straight-on composition, realistic materials, quiet street with no people. — generado con Microsoft AI: MAI-Image-2.5

Zona de pruebas

Pruebas de rendimiento

Puntuaciones en evaluaciones estandarizadas y respuestas de este modelo a instrucciones compartidas de las pruebas de referencia. Los porcentajes más altos son mejores, y cada posición indica dónde se sitúa este modelo entre los modelos evaluados en esa fuente.

Resumen de puntuaciones en pruebas de rendimiento de Microsoft AI: MAI-Image-2.5 (Design Arena)
FuentePrueba de rendimientoPuntuación
Design ArenaMAI-Image-2.5 Models Arena Graphic Design Elo1209
Design ArenaMAI-Image-2.5 Models Arena Image Elo1228
Design ArenaMAI-Image-2.5 Models Arena Imageediting Elo1226
Design ArenaMAI-Image-2.5 Models Arena Logo Elo1248

Benchmark outputs summary for Microsoft AI: MAI-Image-2.5

  • Full wine glass: A wine glass filled to the brim with white wine, the surface level with the rim of the glass, standing upright on a plain wooden table. Straight-on eye-level shot, glass upright and not tilted, no other objects in the frame. (Empatado en el puesto 10.º de 60 en este prompt)
  • Closed umbrellas: Wide street-level photograph of about twelve people crossing a city street in heavy rain. Every person is carrying a closed, furled umbrella held down at their side. Not a single umbrella is open. Each umbrella is clearly visible. They are all getting soaked. No other people in the frame. (Empatado en el puesto 4.º de 60 en este prompt)
  • Three fingers: Close straight-on photograph of an open right hand raised palm towards the camera, with exactly three fingers extended straight up and the other two folded down into the palm. Plain background, nothing else in the frame. (Empatado en el puesto 1.º de 60 en este prompt)
  • Cards & dice: Exactly four playing cards face up in a single straight row on a polished marble counter, evenly spaced, all the same size, showing the seven of hearts, the eight of spades, the nine of diamonds and the ten of clubs from left to right. No other objects in the frame. Straight-on eye-level shot, soft even light. (Empatado en el puesto 12.º de 60 en este prompt)
  • Long exact string: A white A4 poster on a brick wall reading exactly "SPRING CLEARANCE - EVERYTHING 40% OFF - SATURDAY 14 JUNE, 9AM TO 6PM". No other text in the frame. (Empatado en el puesto 29.º de 60 en este prompt)
  • Multiple languages: Straight-on photograph of a white overhead directional sign in an international airport terminal, with a black arrow pointing right at the left end. The sign carries the same word in four scripts on four stacked lines, in this order from top to bottom: "DEPARTURES", then the Japanese 出発, then the Korean 출발, then the Arabic المغادرة. Clean sans-serif lettering, sharp focus, no other text anywhere in the frame. (Empatado en el puesto 32.º de 60 en este prompt)
  • Occlusion: Straight-on eye-level photograph of a plain wooden desk. On the left, a closed hardcover book with a dark red cover stands upright, its front cover facing the camera. A blue ceramic mug stands on the desk to the right of the book and clearly further back, about 20 cm behind it, positioned so that the right edge of the book overlaps and hides the left third of the mug. The mug's handle points to the right and the whole rim of the mug is visible. Bare desk surface is visible between the book and the mug. Nothing else on the desk. Plain wall behind, soft even light. (Empatado en el puesto 39.º de 60 en este prompt)
  • Mirror: Straight-on eye-level photograph of a bathroom vanity. A large rectangular mirror covers the wall behind the counter and its bottom edge meets the countertop, so both the objects and their reflections are visible. On the counter, a tall red toothbrush cup on the left and a tall green glass bottle on the right, both roughly 20 cm tall and well apart from each other. The mirror reflects the counter and the objects on it accurately. Nothing else in the frame. (Empatado en el puesto 42.º de 60 en este prompt)
  • Plain zebra: Photograph of a zebra standing side-on in short grass. Its coat is a uniform solid grey with no stripes, no bands and no markings of any kind anywhere on its body. The whole animal is visible. Sharp focus. (Empatado en el puesto 27.º de 60 en este prompt)
  • Times Square: Wide street-level photograph of Times Square in New York at night, wet asphalt reflecting the lights. Every billboard, screen, storefront window, awning, taxi door and road marking is completely blank — lit with plain colour fields and soft gradients only. No letters, no words, no numbers, no logos, no lettering of any kind anywhere in the frame. Sharp focus, straight-on shot. (Empatado en el puesto 11.º de 60 en este prompt)
  • Minimal diff: From the reference photo, change only the sign text to "ROUTE 7 ESPRESSO - OPEN TILL 8". Keep the sign, wall, lighting and framing identical. (Empatado en el puesto 5.º de 60 en este prompt)
  • Object removal: Remove only the second cup from the left in the reference photo. Leave the other four cups exactly as they are, in the same positions, and leave the shelf, towel, wall, plant and lighting untouched. (Empatado en el puesto 33.º de 60 en este prompt)
  • Person removal: In the reference photo, remove only the person in the yellow coat. Their shadow on the pavement and their reflection in the shop window must be removed as well. Reconstruct the pavement and the window glass behind them. The person in the red coat and the person in the green coat must stay completely unchanged, including their own shadows and their own reflections. Change nothing else in the frame. (Empatado en el puesto 1.º de 60 en este prompt)
  • Product placement: Product photograph of the ceramic mug from the reference image, standing upright on a café table. Show the same side of the mug, from the same side-on eye-level angle as the reference, with the handle on the right. The shape, proportions, colours, moulded relief and every painted detail must match the reference exactly. Only the setting and lighting change: soft daylight in a café interior, shallow depth of field. (Empatado en el puesto 1.º de 60 en este prompt)
  • Four references: Place the person from the portrait reference at the desk in the scene reference, wearing the rust orange canvas jacket from its reference and holding the navy blue travel mug from its reference in one hand. Keep the face, the jacket and the mug exactly as they appear in the references — same colours, same details, same proportions. Do not change the room. (Empatado en el puesto 24.º de 60 en este prompt)
  • Portraits: Studio headshot of a woman in a charcoal blazer against a mid-grey seamless backdrop, lit by a large softbox slightly above and to the left with a soft fill from the right, catchlights in both eyes. An 85mm look with shallow depth of field, skin texture and flyaway hairs kept rather than smoothed.
  • People in scenes: Photograph of four cooks working the pass in a restaurant kitchen at service, plating three dishes at once, several hands in frame and some of them overlapping. One cook partly hidden behind another, steam rising into hard overhead light, each face clearly a different person.
  • Animals: Photograph of a tabby cat asleep on a sunlit windowsill, fur lit from behind so the individual hairs glow at the edges, one ear turned toward the camera. Shallow depth of field, a houseplant soft in the background, quiet morning light.
  • Landscape and nature: Photograph of an old-growth temperate rainforest after rain, moss on every trunk and fallen log, ferns dense across the floor, thin fog between the far trees. Overcast light with no direct sun, everything from the nearest fern to the last trunk in focus.

Proveedores

Este modelo está alojado por un único proveedor. OpenRouter le reenvía todas las solicitudes directamente, sin necesidad de tomar decisiones de enrutamiento.

Precios

El precio medio que los clientes pagan realmente por este modelo, junto a los precios que publican los proveedores. El uso de caché y los descuentos hacen que el precio realmente pagado a menudo sea muy inferior al publicado.

Rendimiento

La velocidad de generación indica lo rápido que escribe el modelo (tokens por segundo: cuanto mayor, mejor). La latencia es el tiempo total de ida y vuelta (cuanto menor, mejor). TTFT es el tiempo hasta el primer token: cuánto tarda en aparecer algo en pantalla (cuanto menor, mejor).

Tiempo de actividad

El tiempo de actividad es el porcentaje de los últimos 3 días en que al menos un proveedor respondía a las solicitudes. La disponibilidad es el porcentaje de tiempo en que la inferencia se sirvió correctamente. OpenRouter supervisa continuamente y utiliza el siguiente mejor proveedor cuando uno devuelve un error.

Aplicaciones

Aplicaciones públicas que envían más tráfico a este modelo. Una buena señal de cómo son las cargas de trabajo reales en producción, y una pista sobre los casos de uso para los que este modelo es más adecuado.

Actividad

Volumen de tokens y tráfico de solicitudes a este modelo a lo largo del tiempo.

API

Código listo para usar para llamar a este modelo. La API de OpenRouter es compatible con OpenAI: la mayoría de los SDK funcionan con solo cambiar la URL base. Lo único que cambia entre modelos es el identificador del modelo que aparece a continuación.

Actualmente no está disponible mediante el enrutamiento dentro de la región de la UE. Documentación de enrutamiento dentro de la región

Explorar más modelos

Modelos de IA con visión: LLM multimodales para la comprensión de imágenesColecciónModelos de generación de imágenesColecciónClasificaciones de modelos de imágenesClasificación
Latencia de extremo a extremo
5,00 US$8,00 US$47,00 US$24,21s
100,00 %
Latencia de extremo a extremo
24,21s

P50, mejor proveedor

Tiempo de actividad (3 d)El modelo estaba accesible. Solicitud enrutada a un proveedor.
100,00 %
Disponibilidad (3 d)El modelo devolvió una inferencia de cualquier proveedor. Los errores y las respuestas vacías cuentan en su contra.
99,89 %

Disponibilidad durante los últimos 3 días

Últimas 72 horas
Disponibilidad 99,89 %
Hace 3 díasHace 2 díasAyerAhora

Disponibilidad en las últimas 24 horas

OpenRouter Availability
99,84 %

Cuando se produce un error en un proveedor ascendente, podemos recuperarnos enrutando la solicitud a otro proveedor que funcione correctamente, si los filtros de su solicitud lo permiten. Puede acceder mediante programación a los datos de tiempo de actividad de cada proveedor a través de la API de endpoints. Obtenga más información sobre nuestras opciones de equilibrio de carga y enrutamiento de proveedores.

1.
Favicon de https://i.love.koalas.ai/
KoalaBear
nuevo
79Mtókenes
2.
Favicon de https://daciel.com/
Daciel
nuevo
722Któkenes
3.
Favicon de https://feed.xomnia.com/
Xomnia GenAI cover image
nuevo
556Któkenes
4.
Favicon de https://demo.marketjs-cloud.com/
Steam Achievements Icon Maker Web
nuevo
323Któkenes
5.
Favicon de https://propanemedia.xyz/
Propane Longform Studio
nuevo
94Któkenes

Preguntas frecuentes

Microsoft AI's MAI-Image-2.5 is a high-quality image generation model available via Azure AI Foundry. It produces photorealistic and artistic images from text prompts with support for various aspect ratios.

MAI-Image-2.5 cuesta 5,00 US$/M tokens por Text Input, 8,00 US$/M tokens por Image Input y 47,00 US$/M tokens por Image Output.

MAI-Image-2.5 admite las relaciones de aspecto 1:1, 4:3, 3:4, 16:9, 9:16, 3:2 y 1 más.

MAI-Image-2.5 acepta texto e imágenes como entrada y devuelve imágenes. Se pueden adjuntar hasta 1 imagen de referencia a una solicitud de edición de imágenes.

MAI-Image-2.6, MAI-Image-2.6 Flash y MAI-Image-2.5 Pro son otros modelos de imagen de Microsoft.

MAI-Image-2.5 se lanzó el 2 de junio de 2026.

Más modelos de Microsoft

Microsoft-Decision-1

Microsoft-Decision-1 is a small model built for fast decision-making. Instead of generating text, it reads the provided content and returns a calibrated probability for each fixed answer option, so the response carries its own confidence and can determine when an application acts, defers, or asks for review. It is post-trained from Qwen3.5-9B for single-pass scoring and suited to classification, routing, prioritization, verification, workflow control, agent guardrails, and AI judging. It is not intended for open-ended generation, conversation, translation, or summarization. Weights are updated continually while the API shape stays the same.

Learn more in Microsoft's announcement: https://commandline.microsoft.com/microsoft-decision-1-model-foundry/

Decisiones0,042 US$ / 0 US$
MAI-Voice-2.1-Flash

MAI-Voice-2.1-Flash is a low-latency text-to-speech model from Microsoft AI, optimized for real-time responsiveness. It produces natural, expressive speech across 23 languages, with human-like intonation, rhythm, and emotional nuance. It is suited for voice agents, assistants, call centers, and other interactive applications where latency and cost matter most.

On OpenRouter, set voice to a full voice ID with the model suffix, such as "en-US-Harper:MAI-Voice-2.1-Flash". A voice's locale sets the synthesis language. Set response_format to "mp3" or "pcm" (24 kHz mono). Harper and Grant support the agent, customer-call-center, educational, and narrator speaking styles, and many locale voices add emotion styles such as excited, happy, sad, and whispering. The full list of voices is in the supported_voices field of the models API. See the text-to-speech guide.
Voz15 US$/M characters
MAI-Voice-2.1

MAI-Voice-2.1 is Microsoft AI's highest-fidelity, most expressive text-to-speech model. It produces natural, studio-grade speech across 23 languages, with detailed prosody, nuanced expressiveness, and speaker consistency over long-form content. It is suited for audiobooks, podcasts, lectures, narration, and brand audio where maximum voice quality matters. The model prioritizes naturalness and expressivity over latency-critical generation.

On OpenRouter, set voice to a full voice ID with the model suffix, such as "en-US-Harper:MAI-Voice-2.1". A voice's locale sets the synthesis language. Set response_format to "mp3" or "pcm" (24 kHz mono). Harper and Grant support the agent, customer-call-center, educational, and narrator speaking styles, and many locale voices add emotion styles such as excited, happy, sad, and whispering. The full list of voices is in the supported_voices field of the models API. See the text-to-speech guide.

Voz22 US$/M characters
MAI-Image-2.6

MAI-Image-2.6 is an image generation and editing model from Microsoft AI, the precision tier of the MAI-Image-2.6 family alongside the faster MAI-Image-2.6 Flash. It is suited for design-ready visuals and controlled, iterative editing, and is particularly strong at multi-reference editing that combines people, products, styles, and scenes from up to five input images while preserving composition, style, and detail. Aspect ratio can be fixed or left to the model to choose for the composition.

Imagen8 US$ / 38 US$
MAI-Image-2.6 Flash

MAI-Image-2.6 Flash is the lower-latency, lower-cost member of the MAI-Image-2.6 family from Microsoft AI, built for latency-sensitive, high-throughput production image generation and editing at comparable quality to the precision tier. It supports the same multi-reference editing with up to five input images and the same fixed or model-chosen aspect ratios.

Imagen2,50 US$ / 19 US$
MAI-Transcribe 2

MAI-Transcribe 2 is a multilingual speech-to-text model from Microsoft AI, ranked #1 on the FLEURS multilingual benchmark. It supports 60 languages with automatic language identification, code switching for mixed-language speech, speaker diarization, word-level timestamps, keyword biasing for domain-specific terminology, and configurable verbatim or clean transcription styles. It is suited for captions, call transcription, subtitling, accessibility, and other voice-enabled applications, and is faster than MAI-Transcribe-1.5 on long-form audio.

On OpenRouter, set response_format to "verbose_json" for segment timestamps, and add timestamp_granularities: ["word"] for word-level timestamps. Set provider.options.azure.diarization.enabled to true for speaker labels, provide keywords through provider.options.azure.phraseList.phrases, and select a transcription style through provider.options.azure.enhancedMode.modelOptions.transcribeStyle. See the speech-to-text guide.

Transcripción0,10 US$/hour
MAI-Image-2.5 Pro

Microsoft AI's MAI-Image-2.5 is a high-quality image generation model available via Azure AI Foundry. It produces photorealistic and artistic images from text prompts with support for various aspect ratios.

Imagen8 US$ / 108 US$
MAI-Voice-2-Flash

MAI-Voice-2-Flash is a low-latency text-to-speech model from Microsoft AI for voice agents, assistants, call centers, accessibility, narration, and other interactive applications. It generates expressive 24 kHz mono speech across 15 languages and 18 locales, with fine-grained control over tone and delivery. Voice prompting and cloning require Microsoft AI-approved access and appropriate speaker consent.

Voz15 US$/M characters
MAI-Voice-2

MAI-Voice-2 is an expressive text-to-speech model from Microsoft AI. It is suited for conversational assistants, media narration, accessibility, education, and other long-form voice applications. It supports 15 languages across 18 locales, fine-grained control of tone and delivery, multi-speaker generation, and voice prompting from short audio clips without fine-tuning. The model prioritizes naturalness and expressivity over latency-critical generation.

Voz22 US$/M characters
MAI-Transcribe 1.5

MAI-Transcribe 1.5 is a multilingual speech-to-text model from Microsoft AI. It is suited for captions, call transcription, subtitling, accessibility, and other voice-enabled applications, with reliable transcription across 43 languages, diverse accents, and noisy real-world audio. It supports automatic language identification and keyword biasing for domain-specific terminology, and improves long-form transcription speed over MAI-Transcribe-1. Speaker diarization is not supported.

Transcripción0,36 US$/hour
Phi 4 Mini Instruct

Phi-4-mini-instruct is a lightweight open model built upon synthetic data and filtered publicly available websites - with a focus on high-quality, reasoning dense data. The model belongs to the Phi-4 model family and supports 128K token context length. The model underwent an enhancement process, incorporating both supervised fine-tuning and direct preference optimization to support precise instruction adherence and robust safety measures.

TextoContexto de 131K
Phi 4 Reasoning Plus

Phi-4-reasoning-plus is an enhanced 14B parameter model from Microsoft, fine-tuned from Phi-4 with additional reinforcement learning to boost accuracy on math, science, and code reasoning tasks. It uses the same dense decoder-only transformer architecture as Phi-4, but generates longer, more comprehensive outputs structured into a step-by-step reasoning trace and final answer.

While it offers improved benchmark scores over Phi-4-reasoning across tasks like AIME, OmniMath, and HumanEvalPlus, its responses are typically ~50% longer, resulting in higher latency. Designed for English-only applications, it is well-suited for structured reasoning workflows where output quality takes priority over response speed.

TextoContexto de 33K
Phi 4 Reasoning

Phi-4-reasoning is a 14B parameter dense decoder-only transformer developed by Microsoft, fine-tuned from Phi-4 to enhance complex reasoning capabilities. It uses a combination of supervised fine-tuning on chain-of-thought traces and reinforcement learning, targeting math, science, and code reasoning tasks. With a 32k context window and high inference efficiency, it is optimized for structured responses in a two-part format: reasoning trace followed by a final solution.

The model achieves strong results on specialized benchmarks such as AIME, OmniMath, and LiveCodeBench, outperforming many larger models in structured reasoning tasks. It is released under the MIT license and intended for use in latency-constrained, English-only environments requiring reliable step-by-step logic. Recommended usage includes ChatML prompts and structured reasoning format for best results.

TextoContexto de 33K
MAI DS R1

MAI-DS-R1 is a post-trained variant of DeepSeek-R1 developed by the Microsoft AI team to improve the model’s responsiveness on previously blocked topics while enhancing its safety profile. Built on top of DeepSeek-R1’s reasoning foundation, it integrates 110k examples from the Tulu-3 SFT dataset and 350k internally curated multilingual safety-alignment samples. The model retains strong reasoning, coding, and problem-solving capabilities, while unblocking a wide range of prompts previously restricted in R1.

MAI-DS-R1 demonstrates improved performance on harm mitigation benchmarks and maintains competitive results across general reasoning tasks. It surpasses R1-1776 in satisfaction metrics for blocked queries and reduces leakage in harmful content categories. The model is based on a transformer MoE architecture and is suitable for general-purpose use cases, excluding high-stakes domains such as legal, medical, or autonomous systems.

TextoContexto de 164K
Phi 4 Multimodal Instruct

Phi-4 Multimodal Instruct is a versatile 5.6B parameter foundation model that combines advanced reasoning and instruction-following capabilities across both text and visual inputs, providing accurate text outputs. The unified architecture enables efficient, low-latency inference, suitable for edge and mobile deployments. Phi-4 Multimodal Instruct supports text inputs in multiple languages including Arabic, Chinese, English, French, German, Japanese, Spanish, and more, with visual input optimized primarily for English. It delivers impressive performance on multimodal tasks involving mathematical, scientific, and document reasoning, providing developers and enterprises a powerful yet compact model for sophisticated interactive applications. For more information, see the Phi-4 Multimodal blog post.

TextoContexto de 131K
Phi 4

Microsoft Research Phi-4 is designed to perform well in complex reasoning tasks and can operate efficiently in situations with limited memory or where quick responses are needed.

At 14 billion parameters, it was trained on a mix of high-quality synthetic datasets, data from curated websites, and academic materials. It has undergone careful improvement to follow instructions accurately and maintain strong safety standards. It works best with English language inputs.

For more information, please see Phi-4 Technical Report

TextoContexto de 16K0,07 US$ / 0,14 US$
Phi-3.5 Mini 128K Instruct

Phi-3.5 models are lightweight, state-of-the-art open models. These models were trained with Phi-3 datasets that include both synthetic data and the filtered, publicly available websites data, with a focus on high quality and reasoning-dense properties. Phi-3.5 Mini uses 3.8B parameters, and is a dense decoder-only transformer model using the same tokenizer as Phi-3 Mini.

The models underwent a rigorous enhancement process, incorporating both supervised fine-tuning, proximal policy optimization, and direct preference optimization to ensure precise instruction adherence and robust safety measures. When assessed against benchmarks that test common sense, language understanding, math, code, long context and logical reasoning, Phi-3.5 models showcased robust and state-of-the-art performance among models with less than 13 billion parameters.

TextoContexto de 128K
Phi-3 Medium 4K Instruct

Phi-3 4K Medium is a powerful 14-billion parameter model designed for advanced language understanding, reasoning, and instruction following. Optimized through supervised fine-tuning and preference adjustments, it excels in tasks involving common sense, mathematics, logical reasoning, and code processing.

At time of release, Phi-3 Medium demonstrated state-of-the-art performance among lightweight models. In the MMLU-Pro eval, the model even comes close to a Llama3 70B level of performance.

For 128k context length, try Phi-3 Medium 128K.

TextoContexto de 4K
Phi-3 Mini 128K Instruct

Phi-3 Mini is a powerful 3.8B parameter model designed for advanced language understanding, reasoning, and instruction following. Optimized through supervised fine-tuning and preference adjustments, it excels in tasks involving common sense, mathematics, logical reasoning, and code processing.

At time of release, Phi-3 Medium demonstrated state-of-the-art performance among lightweight models. This model is static, trained on an offline dataset with an October 2023 cutoff date.

TextoContexto de 128K
Phi-3 Medium 128K Instruct

Phi-3 128K Medium is a powerful 14-billion parameter model designed for advanced language understanding, reasoning, and instruction following. Optimized through supervised fine-tuning and preference adjustments, it excels in tasks involving common sense, mathematics, logical reasoning, and code processing.

At time of release, Phi-3 Medium demonstrated state-of-the-art performance among lightweight models. In the MMLU-Pro eval, the model even comes close to a Llama3 70B level of performance.

For 4k context length, try Phi-3 Medium 4K.

TextoContexto de 128K

MAI-Image-2.5 cuesta 5,00 US/MtokensporTextInput,8,00 US/M tokens por Text Input, 8,00 US/MtokensporTextInput,8,00 US/M tokens por Image Input y 47,00 US$/M tokens por Image Output.