Saltar al contenido
Alfa
  • Modelos
  • Clasificaciones
  • Ori
Hablar con ventas

Pie de página

OpenRouterOpenRouter
© 2026 OpenRouter, Inc

Producto

  • Chat
  • Clasificaciones
  • Pruebas de rendimiento
  • Aplicaciones
  • Descubrir
  • Modelos
  • Ori
  • Colecciones
  • Proveedores
  • Herramientas
  • Precios
  • Business
  • Enterprise
  • Laboratorio

Empresa

  • Acerca de
  • Blog
  • Clientes
  • Empleo
    Empleo
  • Privacidad
  • Términos del servicio
  • Centro de confianza
  • Soporte
  • Compatible con OR
  • Datos
  • Marca

Desarrollador

  • Documentación
  • Referencia de la API
  • Plataforma para desarrolladores
  • Estado
  • Mapa del sitio para IA

Conectar

  • Discord
  • GitHub
  • LinkedIn
  • X
  • YouTube
Favicon de openai

OpenAI: GPT Image 2.5 Flare

openai/gpt-image-2.5-flare

Pruebas de rendimientoComparar

GPT Image 2.5 Flare is an image generation and editing model from OpenAI, positioned as the speed-oriented tier of the GPT Image 2.5 series. It is suited to high-volume everyday generation, creator content, and rapid prototyping via the dedicated Images API.

Modalidades
Precio de entrada / salida
8 US$ / 30 US$por 1M
Contexto
400K
Publicado
9 sept 2026
Pruebas de rendimientoComparar
Zona de pruebasPruebas de rendimientoProveedoresPreciosRendimientoTiempo de actividadAplicacionesActividadPreguntas frecuentesExplorar

Example outputs summary for OpenAI: GPT Image 2.5 Flare

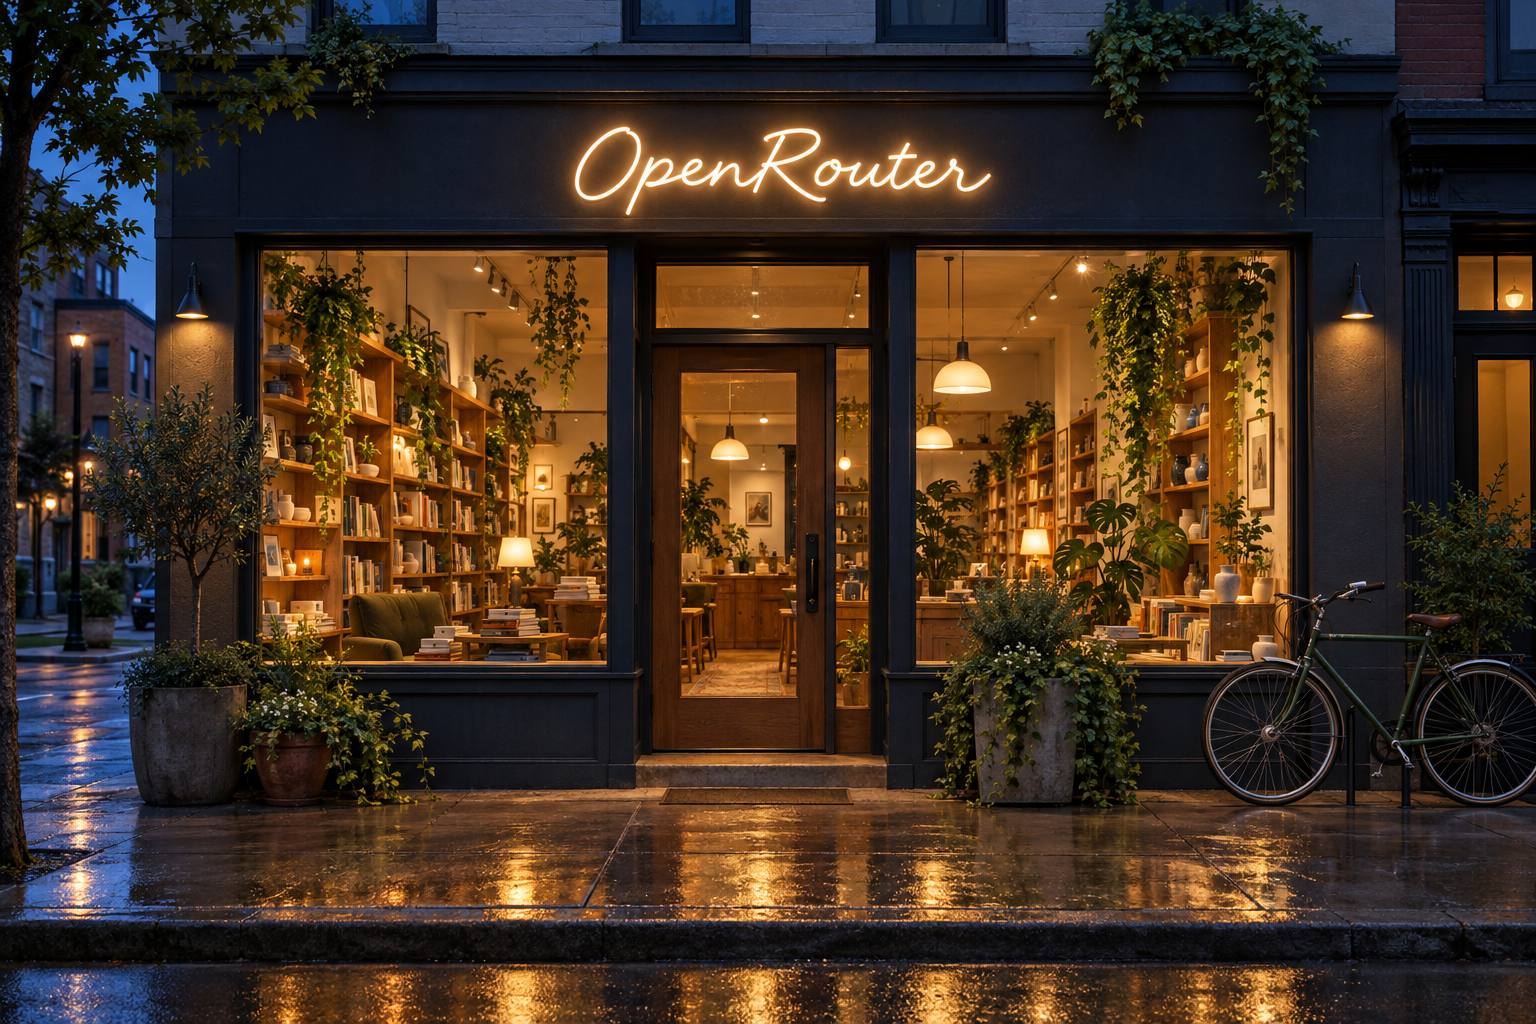
  • Texto a imagen: Editorial architectural photograph of a contemporary neighborhood storefront at blue hour, glowing warmly against the dusk. Above the entrance, a warm-white neon sign in flowing hand-bent cursive reads exactly "OpenRouter", the only text in the scene. Large windows reveal a cozy, lived-in interior: wood shelves styled with books and ceramics, lush trailing plants, and soft pendant lighting. Potted plants and a bicycle rest by the entrance, and golden light spills across the wet pavement in gentle reflections. Straight-on composition, realistic materials, quiet street with no people. — generado con OpenAI: GPT Image 2.5 Flare

Zona de pruebas

Pruebas de rendimiento

Puntuaciones en evaluaciones estandarizadas y respuestas de este modelo a instrucciones compartidas de las pruebas de referencia. Los porcentajes más altos son mejores, y cada posición indica dónde se sitúa este modelo entre los modelos evaluados en esa fuente.

Benchmark outputs summary for OpenAI: GPT Image 2.5 Flare

  • Full wine glass: A wine glass filled to the brim with white wine, the surface level with the rim of the glass, standing upright on a plain wooden table. Straight-on eye-level shot, glass upright and not tilted, no other objects in the frame. (Empatado en el puesto 1.º de 60 en este prompt)
  • Closed umbrellas: Wide street-level photograph of about twelve people crossing a city street in heavy rain. Every person is carrying a closed, furled umbrella held down at their side. Not a single umbrella is open. Each umbrella is clearly visible. They are all getting soaked. No other people in the frame. (Empatado en el puesto 4.º de 60 en este prompt)
  • Three fingers: Close straight-on photograph of an open right hand raised palm towards the camera, with exactly three fingers extended straight up and the other two folded down into the palm. Plain background, nothing else in the frame. (Empatado en el puesto 1.º de 60 en este prompt)
  • Cards & dice: Exactly four playing cards face up in a single straight row on a polished marble counter, evenly spaced, all the same size, showing the seven of hearts, the eight of spades, the nine of diamonds and the ten of clubs from left to right. No other objects in the frame. Straight-on eye-level shot, soft even light. (Empatado en el puesto 1.º de 60 en este prompt)
  • Long exact string: A white A4 poster on a brick wall reading exactly "SPRING CLEARANCE - EVERYTHING 40% OFF - SATURDAY 14 JUNE, 9AM TO 6PM". No other text in the frame. (Empatado en el puesto 29.º de 60 en este prompt)
  • Multiple languages: Straight-on photograph of a white overhead directional sign in an international airport terminal, with a black arrow pointing right at the left end. The sign carries the same word in four scripts on four stacked lines, in this order from top to bottom: "DEPARTURES", then the Japanese 出発, then the Korean 출발, then the Arabic المغادرة. Clean sans-serif lettering, sharp focus, no other text anywhere in the frame. (Empatado en el puesto 1.º de 60 en este prompt)
  • Occlusion: Straight-on eye-level photograph of a plain wooden desk. On the left, a closed hardcover book with a dark red cover stands upright, its front cover facing the camera. A blue ceramic mug stands on the desk to the right of the book and clearly further back, about 20 cm behind it, positioned so that the right edge of the book overlaps and hides the left third of the mug. The mug's handle points to the right and the whole rim of the mug is visible. Bare desk surface is visible between the book and the mug. Nothing else on the desk. Plain wall behind, soft even light. (Empatado en el puesto 25.º de 60 en este prompt)
  • Mirror: Straight-on eye-level photograph of a bathroom vanity. A large rectangular mirror covers the wall behind the counter and its bottom edge meets the countertop, so both the objects and their reflections are visible. On the counter, a tall red toothbrush cup on the left and a tall green glass bottle on the right, both roughly 20 cm tall and well apart from each other. The mirror reflects the counter and the objects on it accurately. Nothing else in the frame. (Empatado en el puesto 2.º de 60 en este prompt)
  • Plain zebra: Photograph of a zebra standing side-on in short grass. Its coat is a uniform solid grey with no stripes, no bands and no markings of any kind anywhere on its body. The whole animal is visible. Sharp focus. (Empatado en el puesto 1.º de 60 en este prompt)
  • Times Square: Wide street-level photograph of Times Square in New York at night, wet asphalt reflecting the lights. Every billboard, screen, storefront window, awning, taxi door and road marking is completely blank — lit with plain colour fields and soft gradients only. No letters, no words, no numbers, no logos, no lettering of any kind anywhere in the frame. Sharp focus, straight-on shot. (Empatado en el puesto 1.º de 60 en este prompt)
  • Minimal diff: From the reference photo, change only the sign text to "ROUTE 7 ESPRESSO - OPEN TILL 8". Keep the sign, wall, lighting and framing identical. (Empatado en el puesto 5.º de 60 en este prompt)
  • Object removal: Remove only the second cup from the left in the reference photo. Leave the other four cups exactly as they are, in the same positions, and leave the shelf, towel, wall, plant and lighting untouched. (Empatado en el puesto 1.º de 60 en este prompt)
  • Person removal: In the reference photo, remove only the person in the yellow coat. Their shadow on the pavement and their reflection in the shop window must be removed as well. Reconstruct the pavement and the window glass behind them. The person in the red coat and the person in the green coat must stay completely unchanged, including their own shadows and their own reflections. Change nothing else in the frame. (Empatado en el puesto 1.º de 60 en este prompt)
  • Product placement: Product photograph of the ceramic mug from the reference image, standing upright on a café table. Show the same side of the mug, from the same side-on eye-level angle as the reference, with the handle on the right. The shape, proportions, colours, moulded relief and every painted detail must match the reference exactly. Only the setting and lighting change: soft daylight in a café interior, shallow depth of field. (Empatado en el puesto 1.º de 60 en este prompt)
  • Four references: Place the person from the portrait reference at the desk in the scene reference, wearing the rust orange canvas jacket from its reference and holding the navy blue travel mug from its reference in one hand. Keep the face, the jacket and the mug exactly as they appear in the references — same colours, same details, same proportions. Do not change the room. (Empatado en el puesto 1.º de 60 en este prompt)
  • Portraits: Studio headshot of a woman in a charcoal blazer against a mid-grey seamless backdrop, lit by a large softbox slightly above and to the left with a soft fill from the right, catchlights in both eyes. An 85mm look with shallow depth of field, skin texture and flyaway hairs kept rather than smoothed.
  • People in scenes: Photograph of four cooks working the pass in a restaurant kitchen at service, plating three dishes at once, several hands in frame and some of them overlapping. One cook partly hidden behind another, steam rising into hard overhead light, each face clearly a different person.
  • Animals: Photograph of a tabby cat asleep on a sunlit windowsill, fur lit from behind so the individual hairs glow at the edges, one ear turned toward the camera. Shallow depth of field, a houseplant soft in the background, quiet morning light.
  • Landscape and nature: Photograph of an old-growth temperate rainforest after rain, moss on every trunk and fallen log, ferns dense across the floor, thin fog between the far trees. Overcast light with no direct sun, everything from the nearest fern to the last trunk in focus.

Proveedores

Este modelo está alojado por un único proveedor. OpenRouter le reenvía todas las solicitudes directamente, sin necesidad de tomar decisiones de enrutamiento.

Precios

El precio medio que los clientes pagan realmente por este modelo, junto a los precios que publican los proveedores. El uso de caché y los descuentos hacen que el precio realmente pagado a menudo sea muy inferior al publicado.

Rendimiento

La velocidad de generación indica lo rápido que escribe el modelo (tokens por segundo: cuanto mayor, mejor). La latencia es el tiempo total de ida y vuelta (cuanto menor, mejor). TTFT es el tiempo hasta el primer token: cuánto tarda en aparecer algo en pantalla (cuanto menor, mejor).

Tiempo de actividad

El tiempo de actividad es el porcentaje de los últimos 3 días en que al menos un proveedor respondía a las solicitudes. La disponibilidad es el porcentaje de tiempo en que la inferencia se sirvió correctamente. OpenRouter supervisa continuamente y utiliza el siguiente mejor proveedor cuando uno devuelve un error.

Aplicaciones

Aplicaciones públicas que envían más tráfico a este modelo. Una buena señal de cómo son las cargas de trabajo reales en producción, y una pista sobre los casos de uso para los que este modelo es más adecuado.

Actividad

Volumen de tokens y tráfico de solicitudes a este modelo a lo largo del tiempo.

API

Código listo para usar para llamar a este modelo. La API de OpenRouter es compatible con OpenAI: la mayoría de los SDK funcionan con solo cambiar la URL base. Lo único que cambia entre modelos es el identificador del modelo que aparece a continuación.

Actualmente no está disponible mediante el enrutamiento dentro de la región de la UE. Documentación de enrutamiento dentro de la región

Explorar más modelos

Modelos de IA con visión: LLM multimodales para la comprensión de imágenesColecciónModelos de generación de imágenesColecciónClasificaciones de modelos de imágenesClasificación
Latencia de extremo a extremo
5,00 US$8,00 US$30,00 US$2,00 US$12,71s
100,00 %
Latencia de extremo a extremo
12,71s

P50, mejor proveedor

Tiempo de actividad (3 d)El modelo estaba accesible. Solicitud enrutada a un proveedor.
100,00 %
Disponibilidad (3 d)El modelo devolvió una inferencia de cualquier proveedor. Los errores y las respuestas vacías cuentan en su contra.
99,93 %

Disponibilidad durante los últimos 3 días

Últimas 72 horas
Disponibilidad 99,93 %
Hace 3 díasHace 2 díasAyerAhora

Disponibilidad en las últimas 24 horas

OpenRouter Availability
99,96 %

Cuando se produce un error en un proveedor ascendente, podemos recuperarnos enrutando la solicitud a otro proveedor que funcione correctamente, si los filtros de su solicitud lo permiten. Puede acceder mediante programación a los datos de tiempo de actividad de cada proveedor a través de la API de endpoints. Obtenga más información sobre nuestras opciones de equilibrio de carga y enrutamiento de proveedores.

1.
Favicon de https://app.carclean.it/
CarClean
nuevo
199Mtókenes
2.
Favicon de https://getcontent.org/
GetContent
nuevo
78Mtókenes
3.
Favicon de https://github.com/ClosetTheory/ClosetTheoryApp
Closet Theory
nuevo
71,1Mtókenes
4.
Favicon de https://outfoxstories.com/
Outfox Stories
nuevo
39,4Mtókenes
5.
Favicon de https://room-designer.services.biano.com/
room-designer
nuevo
35,5Mtókenes

Preguntas frecuentes

GPT Image 2.5 Flare is an image generation and editing model from OpenAI, positioned as the speed-oriented tier of the GPT Image 2.5 series. It is suited to high-volume everyday generation, creator content, and rapid prototyping via the dedicated Images API.

GPT Image 2.5 Flare cuesta 8,00 US$/M de tokens de entrada y 8,00 US$/M de tókenes de salida, con tarifas independientes para Cache Read a 2,00 US$/M tokens, Text Input a 5,00 US$/M tokens e Image Output a 30,00 US$/M tokens.

GPT Image 2.5 Flare admite las relaciones de aspecto 1:1, 3:2, 2:3, 4:3, 3:4, 16:9 y 2 más y puede generar hasta 10 imágenes por solicitud.

GPT Image 2.5 Flare acepta texto e imágenes como entrada y devuelve imágenes. Se pueden adjuntar hasta 16 imágenes de referencia a una solicitud de edición de imágenes.

GPT Image 2.5 Sunburst, GPT Image 2, GPT Image 1 Mini y 1 más son otros modelos de imagen de OpenAI.

GPT Image 2.5 Flare se lanzó el 9 de septiembre de 2026.

Más modelos de OpenAI

GPT-6.1 Terra Pro

GPT-6.1 Terra Pro is the same underlying model as GPT-6.1 Terra, served with reasoning.mode set to pro for higher-quality responses on complex tasks.

Cost note: pro mode spends far more reasoning tokens per request, so a typical request costs several times more than the same request on GPT-6.1 Terra and takes much longer to complete. It is intended for hard, high-stakes problems where the extra accuracy justifies the cost. For everyday coding, agentic, and chat workloads, use GPT-6.1 Terra instead.

Learn more in OpenAI's docs: https://developers.openai.com/api/docs/guides/reasoning#reasoning-mode

TextoContexto de 1,1M1 US$ / 5 US$
GPT-6.1 Terra Pro (batch)

GPT-6.1 Terra Pro is the same underlying model as GPT-6.1 Terra, served with reasoning.mode set to pro for higher-quality responses on complex tasks.

Cost note: pro mode spends far more reasoning tokens per request, so a typical request costs several times more than the same request on GPT-6.1 Terra and takes much longer to complete. It is intended for hard, high-stakes problems where the extra accuracy justifies the cost. For everyday coding, agentic, and chat workloads, use GPT-6.1 Terra instead.

Learn more in OpenAI's docs: https://developers.openai.com/api/docs/guides/reasoning#reasoning-mode

TextoContexto de 1,1M0,50 US$ / 2,50 US$
GPT-6.1 Terra

GPT-6.1 Terra is the mid-tier model in OpenAI's GPT-6.1 series, priced below GPT-6.1 Sol. It is suited for everyday agentic, coding, and writing work, is particularly strong at understanding screenshots and on-screen content, and is efficient enough for high-volume workloads.

TextoContexto de 1,1M1 US$ / 5 US$
GPT-6.1 Terra (batch)

GPT-6.1 Terra is the mid-tier model in OpenAI's GPT-6.1 series, priced below GPT-6.1 Sol. It is suited for everyday agentic, coding, and writing work, is particularly strong at understanding screenshots and on-screen content, and is efficient enough for high-volume workloads.

TextoContexto de 1,1M0,50 US$ / 2,50 US$
GPT-6 Luna Decisions

GPT-6 Luna Decisions is GPT-6 Luna served through OpenAI's Decisions API. Instead of generating text, it reads the content passed as state (text, JSON, or images) and returns typed, probabilistic answers to named questions in a single request: the probability of yes for a yes/no question (noul), a probability for every option plus the most likely one (choice), or a probability for every level of an ordered rubric plus the expected score (score).

It is built for classification, routing, moderation, and rubric grading where application code thresholds the returned numbers rather than parsing a chat reply. A request can carry up to 200 questions about the same content.

Decisiones0,10 US$ / 0 US$
GPT-6.1 Sol Pro

GPT-6.1 Sol Pro is the same underlying model as GPT-6.1 Sol, served with reasoning.mode set to pro for higher-quality responses on complex tasks.

Cost note: pro mode spends far more reasoning tokens per request, so a typical request costs several times more than the same request on GPT-6.1 Sol and takes much longer to complete. It is intended for hard, high-stakes problems where the extra accuracy justifies the cost. For everyday coding, agentic, and chat workloads, use GPT-6.1 Sol instead.

Learn more in OpenAI's docs: https://developers.openai.com/api/docs/guides/reasoning#reasoning-mode

TextoContexto de 1,1M2 US$ / 10 US$
GPT-6.1 Sol Pro (batch)

GPT-6.1 Sol Pro is the same underlying model as GPT-6.1 Sol, served with reasoning.mode set to pro for higher-quality responses on complex tasks.

Cost note: pro mode spends far more reasoning tokens per request, so a typical request costs several times more than the same request on GPT-6.1 Sol and takes much longer to complete. It is intended for hard, high-stakes problems where the extra accuracy justifies the cost. For everyday coding, agentic, and chat workloads, use GPT-6.1 Sol instead.

Learn more in OpenAI's docs: https://developers.openai.com/api/docs/guides/reasoning#reasoning-mode

TextoContexto de 1,1M1 US$ / 5 US$
GPT-6.1 Sol

GPT-6.1 Sol is an upgrade to GPT-6 Sol from OpenAI, positioned below the flagship GPT-6 Astra in the GPT-6 series. It is suited for agentic coding, computer use, document-heavy professional work, and multi-step business workflow automation, and approaches Astra-level results on these tasks at a much lower cost. Compared with GPT-6 Sol, it makes fewer factual errors and is more reliable at respecting explicit restrictions and user intent during agentic tasks.

TextoContexto de 1,1M2 US$ / 10 US$
GPT-6.1 Sol (batch)

GPT-6.1 Sol is an upgrade to GPT-6 Sol from OpenAI, positioned below the flagship GPT-6 Astra in the GPT-6 series. It is suited for agentic coding, computer use, document-heavy professional work, and multi-step business workflow automation, and approaches Astra-level results on these tasks at a much lower cost. Compared with GPT-6 Sol, it makes fewer factual errors and is more reliable at respecting explicit restrictions and user intent during agentic tasks.

TextoContexto de 1,1M1 US$ / 5 US$
GPT-6 Luna Pro

GPT-6 Luna Pro is the same underlying model as GPT-6 Luna, served with reasoning.mode set to pro for higher-quality responses on complex tasks.

Cost note: pro mode spends far more reasoning tokens per request, so a typical request costs several times more than the same request on GPT-6 Luna and takes much longer to complete. It is intended for hard, high-stakes problems where the extra accuracy justifies the cost. For everyday coding, agentic, and chat workloads, use GPT-6 Luna instead.

Learn more in OpenAI's docs: https://developers.openai.com/api/docs/guides/reasoning#reasoning-mode

TextoContexto de 1,1M0,10 US$ / 0,50 US$
GPT-6 Luna Pro (batch)

GPT-6 Luna Pro is the same underlying model as GPT-6 Luna, served with reasoning.mode set to pro for higher-quality responses on complex tasks.

Cost note: pro mode spends far more reasoning tokens per request, so a typical request costs several times more than the same request on GPT-6 Luna and takes much longer to complete. It is intended for hard, high-stakes problems where the extra accuracy justifies the cost. For everyday coding, agentic, and chat workloads, use GPT-6 Luna instead.

Learn more in OpenAI's docs: https://developers.openai.com/api/docs/guides/reasoning#reasoning-mode

TextoContexto de 1,1M0,05 US$ / 0,25 US$
GPT-6 Luna

GPT-6 Luna is the fast, cost-efficient model in OpenAI's GPT-6 series, positioned below GPT-6 Sol. It is suited for high-volume and latency-sensitive workloads such as chat, classification, and lightweight agentic tasks, and at higher reasoning effort it can take on complex software engineering and computer-use tasks that previously called for a Sol-tier model. It shares the GPT-6 family's gains in factual reliability and its clearer, more concise communication style.

TextoContexto de 1,1M0,10 US$ / 0,50 US$
GPT-6 Luna (batch)

GPT-6 Luna is the fast, cost-efficient model in OpenAI's GPT-6 series, positioned below GPT-6 Sol. It is suited for high-volume and latency-sensitive workloads such as chat, classification, and lightweight agentic tasks, and at higher reasoning effort it can take on complex software engineering and computer-use tasks that previously called for a Sol-tier model. It shares the GPT-6 family's gains in factual reliability and its clearer, more concise communication style.

TextoContexto de 1,1M0,05 US$ / 0,25 US$
GPT-6 Sol Pro

GPT-6 Sol Pro is the same underlying model as GPT-6 Sol, served with reasoning.mode set to pro for higher-quality responses on complex tasks.

Cost note: pro mode spends far more reasoning tokens per request, so a typical request costs several times more than the same request on GPT-6 Sol and takes much longer to complete. It is intended for hard, high-stakes problems where the extra accuracy justifies the cost. For everyday coding, agentic, and chat workloads, use GPT-6 Sol instead.

Learn more in OpenAI's docs: https://developers.openai.com/api/docs/guides/reasoning#reasoning-mode

TextoContexto de 1,1M2 US$ / 10 US$
GPT-6 Sol Pro (batch)

GPT-6 Sol Pro is the same underlying model as GPT-6 Sol, served with reasoning.mode set to pro for higher-quality responses on complex tasks.

Cost note: pro mode spends far more reasoning tokens per request, so a typical request costs several times more than the same request on GPT-6 Sol and takes much longer to complete. It is intended for hard, high-stakes problems where the extra accuracy justifies the cost. For everyday coding, agentic, and chat workloads, use GPT-6 Sol instead.

Learn more in OpenAI's docs: https://developers.openai.com/api/docs/guides/reasoning#reasoning-mode

TextoContexto de 1,1M1 US$ / 5 US$
GPT-6 Sol

GPT-6 Sol is the cost-efficient high-end model in OpenAI's GPT-6 series, positioned below the flagship GPT-6 Astra and above the fast GPT-6 Luna tier. It is suited for demanding professional work, agentic coding, business workflow automation, and computer use, and is particularly strong at long-horizon software engineering tasks in real codebases. It approaches Astra-level factual reliability at a much lower cost and shares Astra's clearer, more concise communication style in technical and coding conversations.

TextoContexto de 1,1M2 US$ / 10 US$
GPT-6 Sol (batch)

GPT-6 Sol is the cost-efficient high-end model in OpenAI's GPT-6 series, positioned below the flagship GPT-6 Astra and above the fast GPT-6 Luna tier. It is suited for demanding professional work, agentic coding, business workflow automation, and computer use, and is particularly strong at long-horizon software engineering tasks in real codebases. It approaches Astra-level factual reliability at a much lower cost and shares Astra's clearer, more concise communication style in technical and coding conversations.

TextoContexto de 1,1M1 US$ / 5 US$
GPT Astra Latest

This model always redirects to the latest model in the GPT Astra family.

TextoContexto de 1,1M
GPT Sol Latest

This model always redirects to the latest model in the GPT Sol family.

TextoContexto de 1,1M
GPT Terra Latest

This model always redirects to the latest model in the GPT Terra family.

TextoContexto de 1,1M

GPT Image 2.5 Flare cuesta 8,00 US/Mdetokensdeentraday8,00 US/M de tokens de entrada y 8,00 US/Mdetokensdeentraday8,00 US/M de tókenes de salida, con tarifas independientes para Cache Read a 2,00 US/Mtokens,TextInputa5,00 US/M tokens, Text Input a 5,00 US/Mtokens,TextInputa5,00 US/M tokens e Image Output a 30,00 US$/M tokens.