コンテンツへスキップ
アルファ版
  • モデル
  • ランキング
  • Ori
営業担当に相談

フッター

OpenRouterOpenRouter
© 2026 OpenRouter, Inc

製品

  • チャット
  • ランキング
  • ベンチマーク
  • アプリ
  • 見つける
  • モデル
  • Ori
  • コレクション
  • プロバイダー
  • ツール
  • 料金
  • Business
  • Enterprise
  • ラボ

会社情報

  • 概要
  • ブログ
  • お客様
  • 採用情報
    採用情報
  • プライバシー
  • 利用規約
  • トラストセンター
  • サポート
  • OR 対応
  • データ
  • ブランド

開発者

  • ドキュメント
  • API リファレンス
  • 開発者プラットフォーム
  • ステータス
  • AI サイトマップ

接続

  • Discord
  • GitHub
  • LinkedIn
  • X
  • YouTube
meta のファビコン

Meta: Muse Image

meta/muse-image

ベンチマーク比較

Muse Image is an agentic image generation model from Meta that generates and edits images from text and reference images. Unlike single-pass image models, it reasons before it renders, breaking down multi-part prompts and refining its output within the chain of thought, and invokes web search for factual accuracy on knowledge-intensive prompts.

The model supports text-to-image generation, targeted image editing, multi-image composition, reference-image conditioning for style and subject consistency across a series, and precise text rendering within generated images. Iterative editing works by passing the previous output image back with a new instruction.

モダリティ
価格
$0.01/image
コンテキスト
66K
公開日
2026年8月26日
ベンチマーク比較
プレイグラウンドベンチマークプロバイダー料金パフォーマンス稼働率アプリアクティビティよくある質問探索

Example outputs summary for Meta: Muse Image

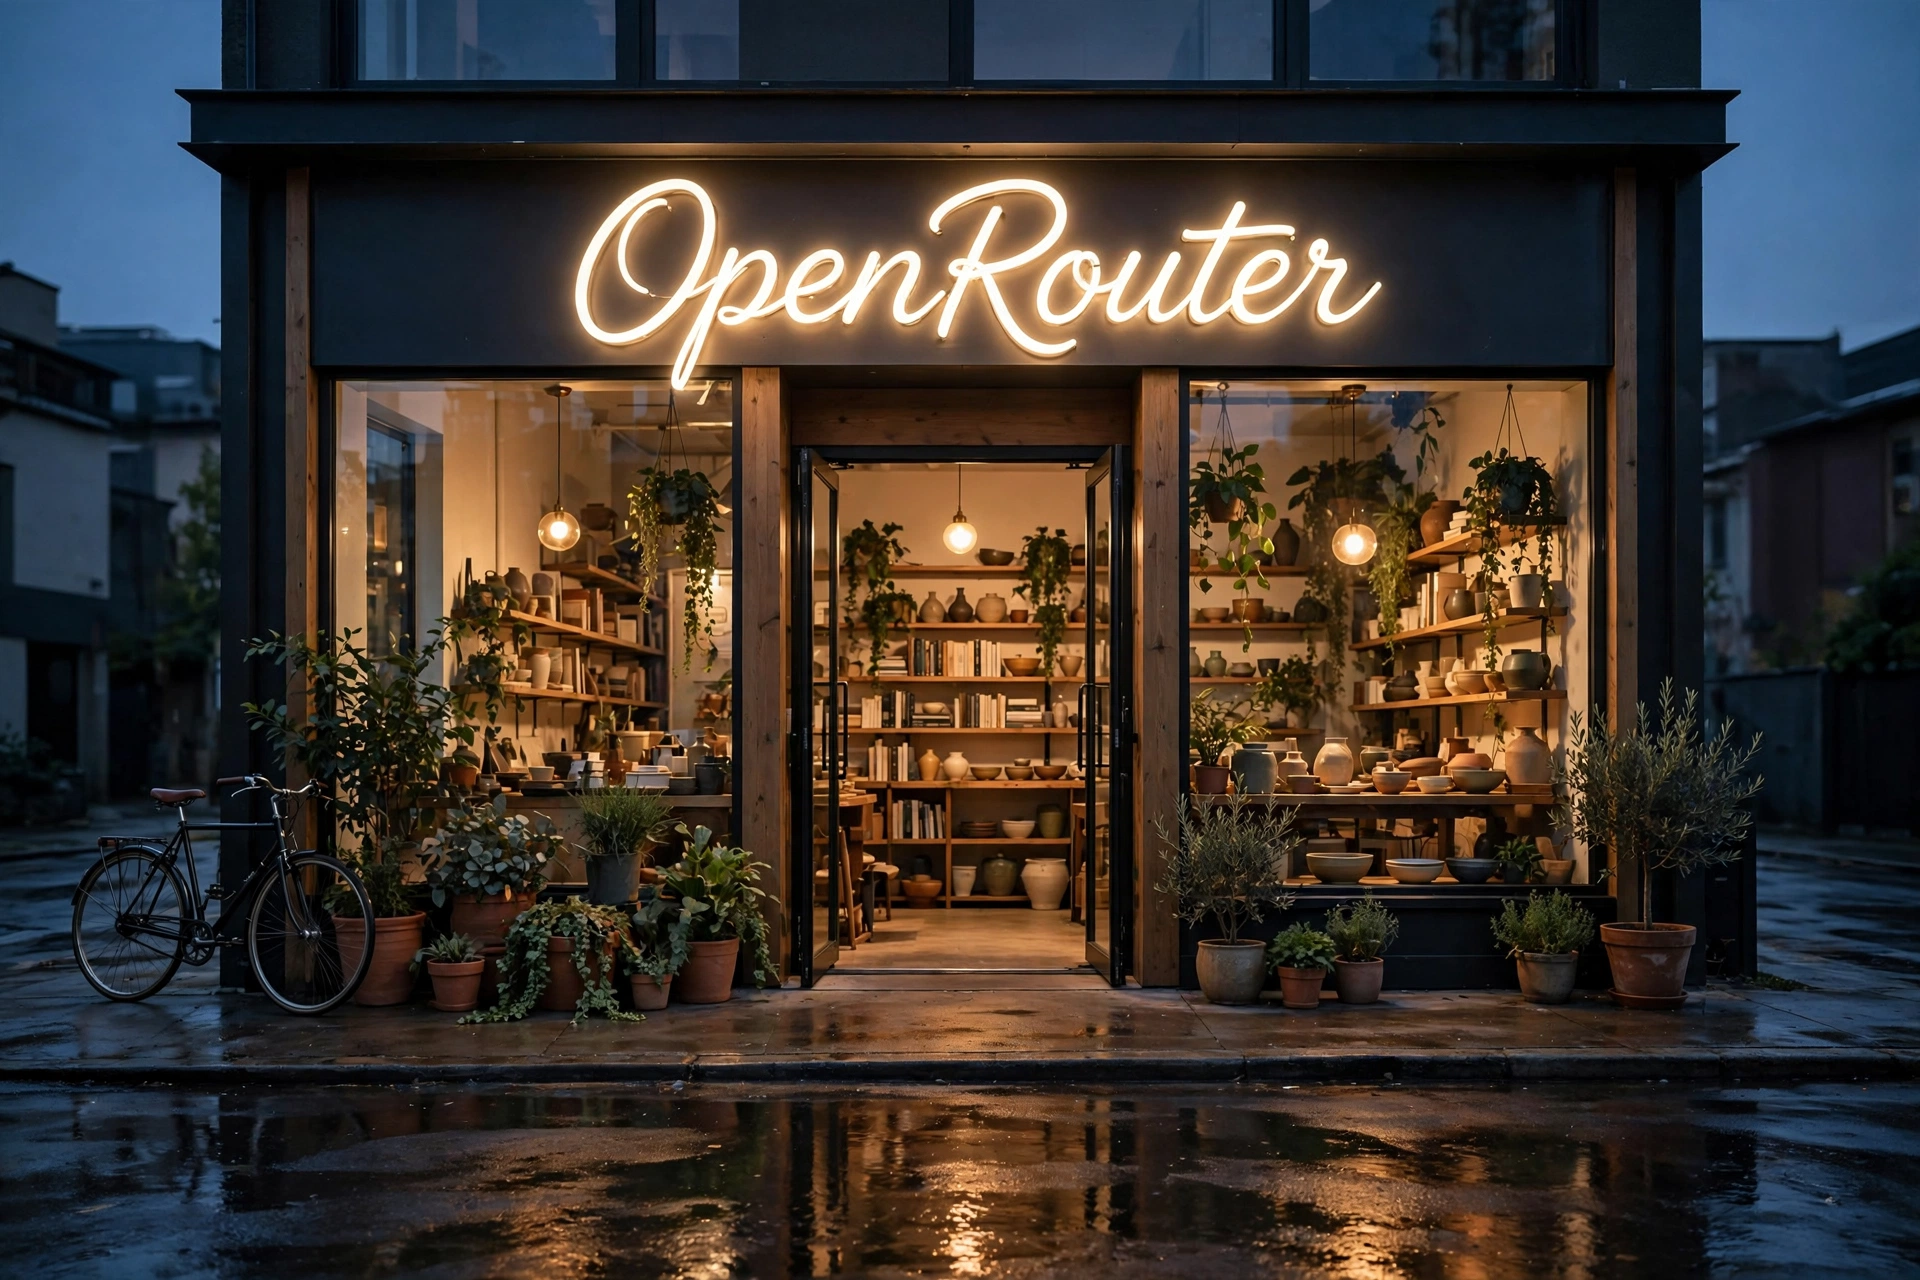
  • テキストから画像生成: Editorial architectural photograph of a contemporary neighborhood storefront at blue hour, glowing warmly against the dusk. Above the entrance, a warm-white neon sign in flowing hand-bent cursive reads exactly "OpenRouter", the only text in the scene. Large windows reveal a cozy, lived-in interior: wood shelves styled with books and ceramics, lush trailing plants, and soft pendant lighting. Potted plants and a bicycle rest by the entrance, and golden light spills across the wet pavement in gentle reflections. Straight-on composition, realistic materials, quiet street with no people. — Meta: Muse Image で生成
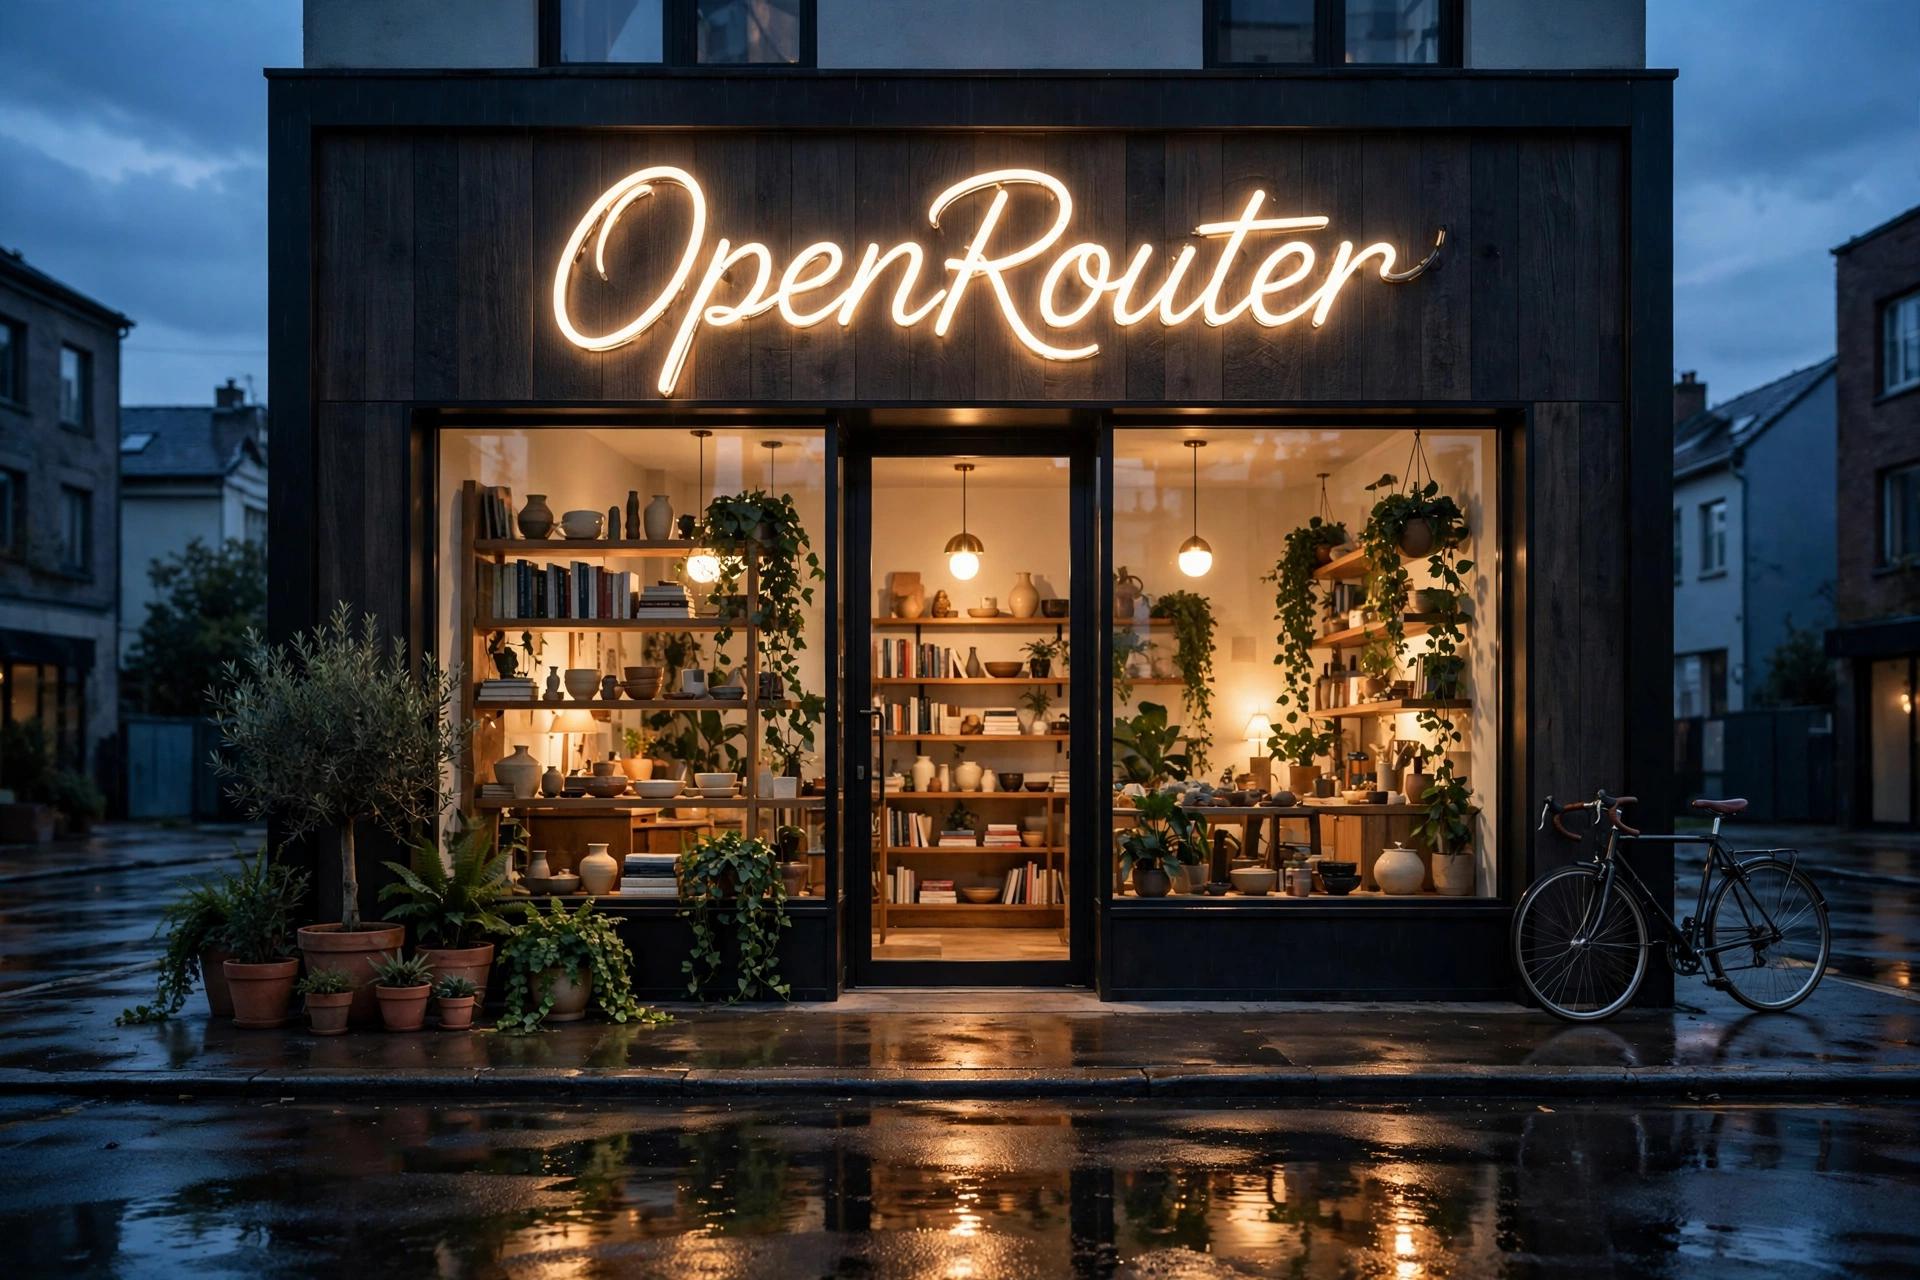
  • テキストから画像生成 2: Editorial architectural photograph of a contemporary neighborhood storefront at blue hour, glowing warmly against the dusk. Above the entrance, a warm-white neon sign in flowing hand-bent cursive reads exactly "OpenRouter", the only text in the scene. Large windows reveal a cozy, lived-in interior: wood shelves styled with books and ceramics, lush trailing plants, and soft pendant lighting. Potted plants and a bicycle rest by the entrance, and golden light spills across the wet pavement in gentle reflections. Straight-on composition, realistic materials, quiet street with no people. — Meta: Muse Image で生成
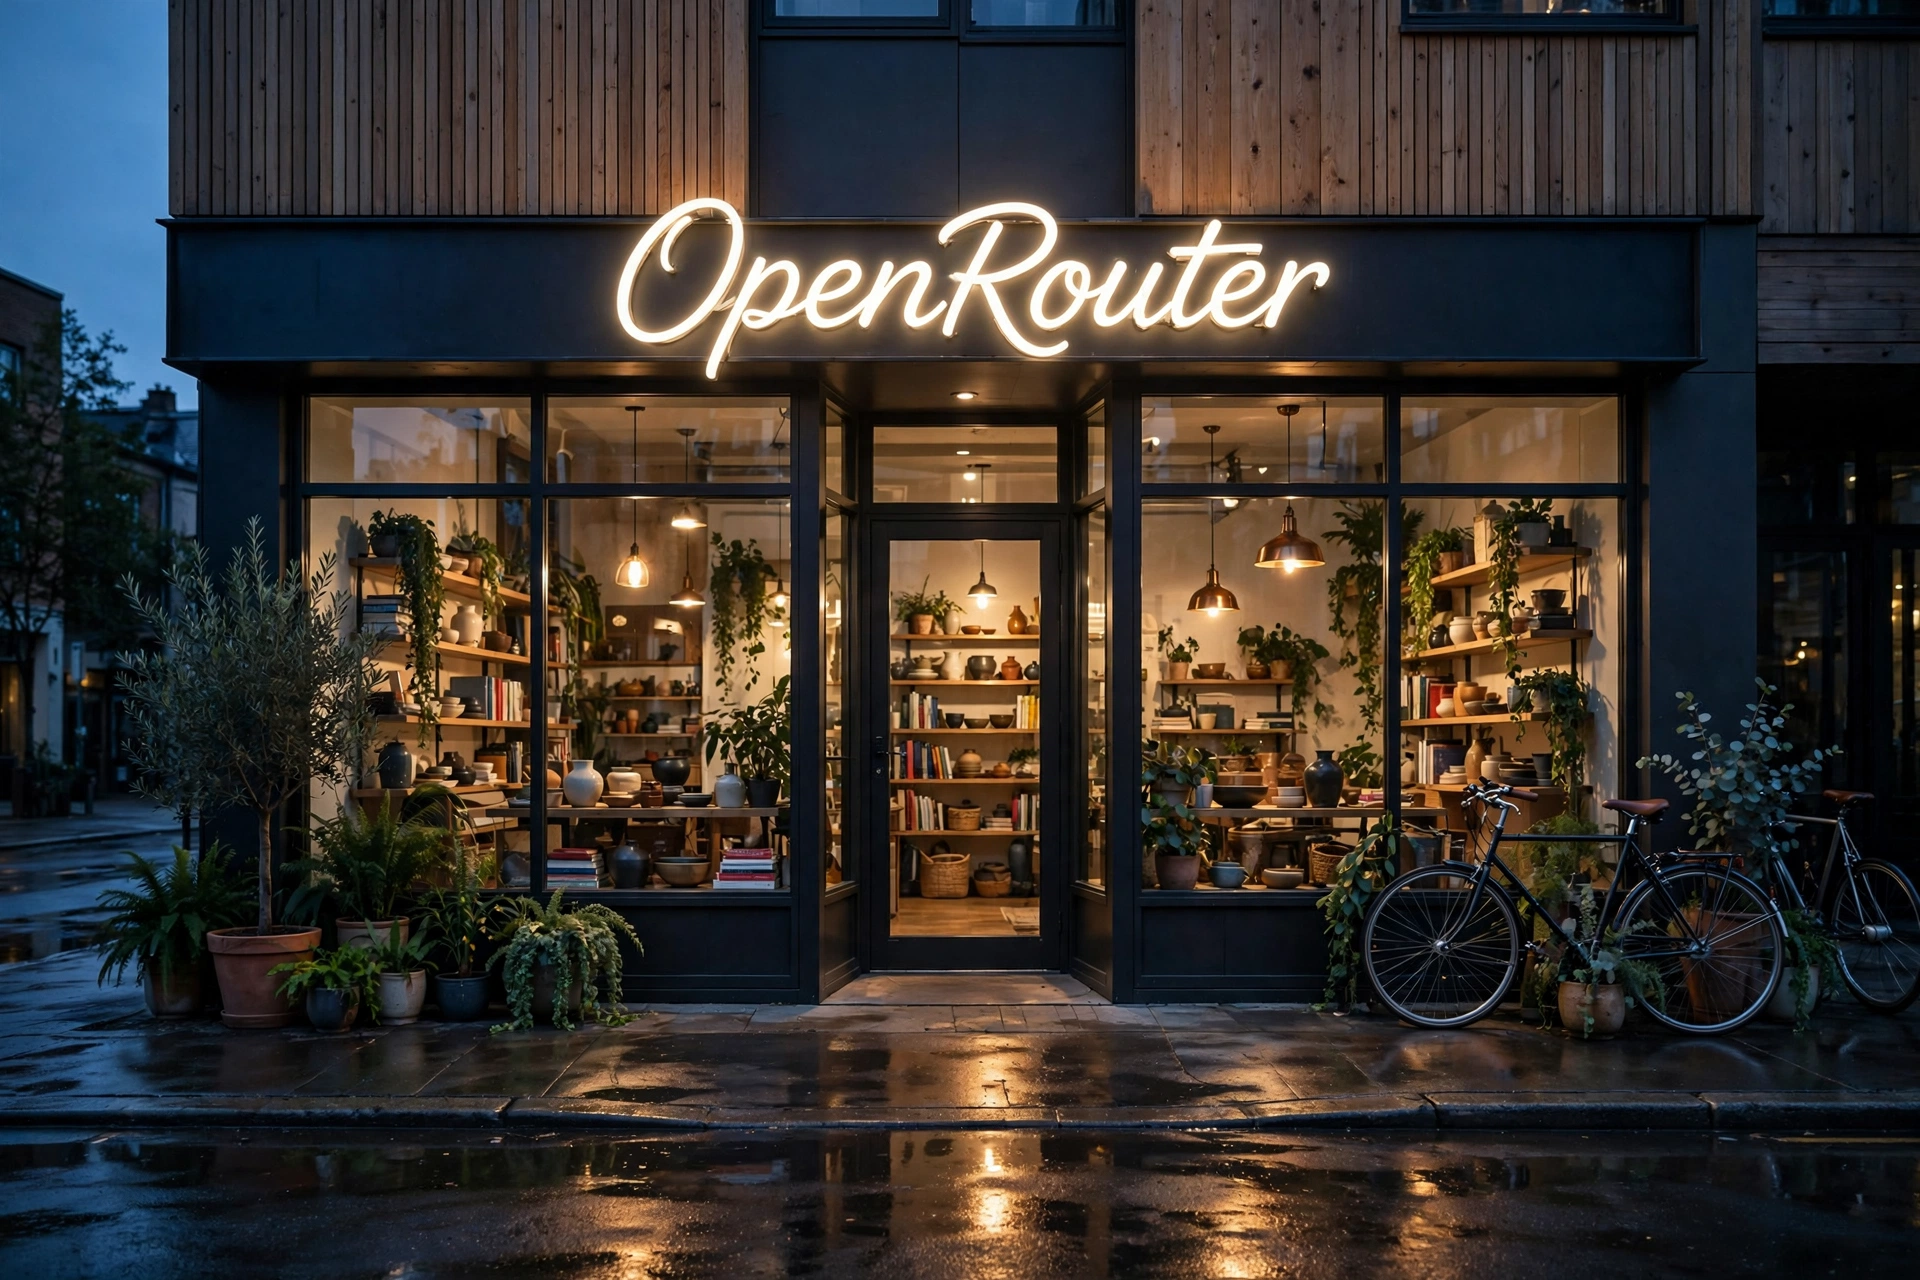
  • テキストから画像生成 3: Editorial architectural photograph of a contemporary neighborhood storefront at blue hour, glowing warmly against the dusk. Above the entrance, a warm-white neon sign in flowing hand-bent cursive reads exactly "OpenRouter", the only text in the scene. Large windows reveal a cozy, lived-in interior: wood shelves styled with books and ceramics, lush trailing plants, and soft pendant lighting. Potted plants and a bicycle rest by the entrance, and golden light spills across the wet pavement in gentle reflections. Straight-on composition, realistic materials, quiet street with no people. — Meta: Muse Image で生成

プレイグラウンド

ベンチマーク

標準化された評価のスコアと、共通のベンチマークプロンプトに対するこのモデル自身の出力です。パーセンテージが高いほど優れており、各順位は、その情報源で評価されたモデルの中でのこのモデルの位置を示します。

Benchmark outputs summary for Meta: Muse Image

  • Full wine glass: A wine glass filled to the brim with white wine, the surface level with the rim of the glass, standing upright on a plain wooden table. Straight-on eye-level shot, glass upright and not tilted, no other objects in the frame. (このプロンプトで 60 件中同率 10 位 位)
  • Closed umbrellas: Wide street-level photograph of about twelve people crossing a city street in heavy rain. Every person is carrying a closed, furled umbrella held down at their side. Not a single umbrella is open. Each umbrella is clearly visible. They are all getting soaked. No other people in the frame. (このプロンプトで 60 件中同率 17 位 位)
  • Three fingers: Close straight-on photograph of an open right hand raised palm towards the camera, with exactly three fingers extended straight up and the other two folded down into the palm. Plain background, nothing else in the frame. (このプロンプトで 60 件中同率 1 位 位)
  • Cards & dice: Exactly four playing cards face up in a single straight row on a polished marble counter, evenly spaced, all the same size, showing the seven of hearts, the eight of spades, the nine of diamonds and the ten of clubs from left to right. No other objects in the frame. Straight-on eye-level shot, soft even light. (このプロンプトで 60 件中同率 1 位 位)
  • Long exact string: A white A4 poster on a brick wall reading exactly "SPRING CLEARANCE - EVERYTHING 40% OFF - SATURDAY 14 JUNE, 9AM TO 6PM". No other text in the frame. (このプロンプトで 60 件中同率 1 位 位)
  • Multiple languages: Straight-on photograph of a white overhead directional sign in an international airport terminal, with a black arrow pointing right at the left end. The sign carries the same word in four scripts on four stacked lines, in this order from top to bottom: "DEPARTURES", then the Japanese 出発, then the Korean 출발, then the Arabic المغادرة. Clean sans-serif lettering, sharp focus, no other text anywhere in the frame. (このプロンプトで 60 件中同率 1 位 位)
  • Occlusion: Straight-on eye-level photograph of a plain wooden desk. On the left, a closed hardcover book with a dark red cover stands upright, its front cover facing the camera. A blue ceramic mug stands on the desk to the right of the book and clearly further back, about 20 cm behind it, positioned so that the right edge of the book overlaps and hides the left third of the mug. The mug's handle points to the right and the whole rim of the mug is visible. Bare desk surface is visible between the book and the mug. Nothing else on the desk. Plain wall behind, soft even light. (このプロンプトで 60 件中同率 1 位 位)
  • Mirror: Straight-on eye-level photograph of a bathroom vanity. A large rectangular mirror covers the wall behind the counter and its bottom edge meets the countertop, so both the objects and their reflections are visible. On the counter, a tall red toothbrush cup on the left and a tall green glass bottle on the right, both roughly 20 cm tall and well apart from each other. The mirror reflects the counter and the objects on it accurately. Nothing else in the frame. (このプロンプトで 60 件中同率 2 位 位)
  • Plain zebra: Photograph of a zebra standing side-on in short grass. Its coat is a uniform solid grey with no stripes, no bands and no markings of any kind anywhere on its body. The whole animal is visible. Sharp focus. (このプロンプトで 60 件中同率 19 位 位)
  • Times Square: Wide street-level photograph of Times Square in New York at night, wet asphalt reflecting the lights. Every billboard, screen, storefront window, awning, taxi door and road marking is completely blank — lit with plain colour fields and soft gradients only. No letters, no words, no numbers, no logos, no lettering of any kind anywhere in the frame. Sharp focus, straight-on shot. (このプロンプトで 60 件中同率 11 位 位)
  • Minimal diff: From the reference photo, change only the sign text to "ROUTE 7 ESPRESSO - OPEN TILL 8". Keep the sign, wall, lighting and framing identical. (このプロンプトで 60 件中同率 5 位 位)
  • Object removal: Remove only the second cup from the left in the reference photo. Leave the other four cups exactly as they are, in the same positions, and leave the shelf, towel, wall, plant and lighting untouched. (このプロンプトで 60 件中同率 1 位 位)
  • Person removal: In the reference photo, remove only the person in the yellow coat. Their shadow on the pavement and their reflection in the shop window must be removed as well. Reconstruct the pavement and the window glass behind them. The person in the red coat and the person in the green coat must stay completely unchanged, including their own shadows and their own reflections. Change nothing else in the frame. (このプロンプトで 60 件中同率 1 位 位)
  • Product placement: Product photograph of the ceramic mug from the reference image, standing upright on a café table. Show the same side of the mug, from the same side-on eye-level angle as the reference, with the handle on the right. The shape, proportions, colours, moulded relief and every painted detail must match the reference exactly. Only the setting and lighting change: soft daylight in a café interior, shallow depth of field. (このプロンプトで 60 件中同率 1 位 位)
  • Four references: Place the person from the portrait reference at the desk in the scene reference, wearing the rust orange canvas jacket from its reference and holding the navy blue travel mug from its reference in one hand. Keep the face, the jacket and the mug exactly as they appear in the references — same colours, same details, same proportions. Do not change the room. (このプロンプトで 60 件中同率 18 位 位)
  • Portraits: Studio headshot of a woman in a charcoal blazer against a mid-grey seamless backdrop, lit by a large softbox slightly above and to the left with a soft fill from the right, catchlights in both eyes. An 85mm look with shallow depth of field, skin texture and flyaway hairs kept rather than smoothed.
  • People in scenes: Photograph of four cooks working the pass in a restaurant kitchen at service, plating three dishes at once, several hands in frame and some of them overlapping. One cook partly hidden behind another, steam rising into hard overhead light, each face clearly a different person.
  • Animals: Photograph of a tabby cat asleep on a sunlit windowsill, fur lit from behind so the individual hairs glow at the edges, one ear turned toward the camera. Shallow depth of field, a houseplant soft in the background, quiet morning light.
  • Landscape and nature: Photograph of an old-growth temperate rainforest after rain, moss on every trunk and fallen log, ferns dense across the floor, thin fog between the far trees. Overcast light with no direct sun, everything from the nearest fern to the last trunk in focus.

プロバイダー

このモデルは 1 社のプロバイダーがホストしています。OpenRouter はすべてのリクエストをそのプロバイダーに直接転送するため、ルーティングの判断は不要です。

料金

プロバイダーが提示する価格と並べて、このモデルに対して顧客が実際に支払う平均価格を表示しています。キャッシュと割引により、実際の支払価格は表示価格を大幅に下回ることがよくあります。

パフォーマンス

スループットはモデルが出力する速さです(毎秒のトークン数で、数値が高いほど優れています)。レイテンシは往復にかかる合計時間です(短いほど優れています)。TTFT は最初のトークンが出力されるまでの時間、つまり何かが表示され始めるまでの時間です(短いほど優れています)。

稼働率

稼働率は、過去 3 日間に少なくとも一社のプロバイダーがリクエストに応答していた時間の割合です。可用性は、推論が正常に提供された時間の割合です。OpenRouter は継続的に監視し、プロバイダーがエラーを返すと、次に最適なプロバイダーを使用します。

アプリ

このモデルに最も多くのトラフィックを送信している公開アプリです。実際の本番ワークロードを把握するための有力な指標であり、このモデルに最も適したユースケースを知る手がかりにもなります。

アクティビティ

このモデルのトークン量とリクエストトラフィックの経時変化です。

API

このモデルを呼び出すために、そのまま使えるコードです。OpenRouter の API は OpenAI 互換のため、ほとんどの SDK はベース URL を変更するだけで動作します。モデル間で変わるのは、下記のモデルスラッグだけです。

現在、EU 域内ルーティングでは利用できません。 リージョン内ルーティングのドキュメント

さらにモデルを探す

視覚機能を備えた AI モデル:画像理解のためのマルチモーダル LLMコレクション画像生成モデルコレクション画像モデルランキングランキング
エンドツーエンドのレイテンシ
$0.0118.13s
99.97%
エンドツーエンドのレイテンシ
18.13秒

P50、最適なプロバイダー

稼働率(3 日間)モデルに接続できました。リクエストはプロバイダーにルーティングされました。
99.99%
可用性(3 日間)モデルがいずれかのプロバイダーから推論結果を返しました。エラーと空のレスポンスはマイナスとして集計されます。
99.07%

過去 3 日間の可用性

過去 72 時間
可用性 99.07%
3 日前2 日前昨日現在

過去 24 時間の可用性

OpenRouter Availability
98.97%

上流のプロバイダーでエラーが発生した場合、リクエストフィルターが許可していれば、別の正常なプロバイダーにルーティングして復旧できます。プロバイダーごとの稼働率データにプログラムでアクセスするには Endpoints APIを利用できます。詳しくは、 負荷分散とプロバイダールーティングのオプションをご覧ください。

1.
https://www.lepetitheros.com/ のファビコン
Le Petit H�ros
新着
510Mトークン
2.
https://playgroundai.com/ のファビコン
Playground
新着
201Mトークン
3.
https://www.hayailearn.com/ のファビコン
HayaiLearn
新着
118Mトークン
4.
https://word-ministries.com/ のファビコン
Word Ministries
新着
102Mトークン
5.
https://foks.pipeline/ のファビコン
FOKS Pipeline
新着
60.7Mトークン

よくある質問

Muse Image is an agentic image generation model from Meta that generates and edits images from text and reference images. Unlike single-pass image models, it reasons before it renders, breaking down multi-part prompts and refining its output within the chain of thought, and invokes web search for factual accuracy on knowledge-intensive prompts.

Muse Image の料金は $0.01/image です。

Muse Image は テキスト、画像 を入力として受け取り、画像 を返します。

Muse Image は 2026年8月26日 にリリースされました。

その他のモデル:提供元 Meta

Muse Spark Open

Muse Spark Open is a coding-optimized open-weight model. Trained specifically for agentic coding workflows, it delivers higher first-attempt accuracy, reliable tool calling, and deep codebase understanding across the repos developers actually work in.

テキスト1.0M コンテキスト$1.25 / $4.25
Muse Wonder

Muse Wonder is a frontier reasoning model from Meta, designed for complex personal and professional agentic tasks. It accepts text, images, video, audio, and PDF documents and returns text, with a 1M-token context window.

The model handles long-horizon work: it plans, delegates to sub-agents, calls tools in parallel, and recovers from errors, so multi-step tasks run to completion without step-by-step direction. It can also operate browsers and desktop and mobile applications, and works across many files in existing repositories to make and verify changes. Muse Wonder carries important context across conversations and retrieves the details relevant to the task at hand. And it's trained for Active Focus, so it works toward your goal even when a task gets challenging.

In Meta's testing, it performs well on complex engineering tasks, extended agentic sessions, and multi-file refactors to tackle developers' most demanding work.

テキスト1.0M コンテキスト$4 / $20
Muse Voice Transcribe 1.0

Muse Voice Transcribe 1.0 is a synchronous speech-to-text model from Meta. It is suited for push-to-talk, endpointing, and speaker-aware transcription, with keyword biasing for domain terms and language biasing through language-name hints. It accepts mono 16-bit PCM WAV audio at 16 kHz or 24 kHz for recordings up to 10 minutes. It does not provide word-level timestamps or confidence scores, and other audio formats must be converted to WAV before upload.

文字起こし$0.00005/second
Muse Spark 1.3 Contributor

Muse Spark 1.3 Contributor is the cost-efficient contributor tier of Meta’s multimodal reasoning model for experimentation, learning, and early-stage agentic, multi-agent, and coding workflows. It is designed to track information across extended tasks, work through conflicting inputs, and request clarification or confirmation when needed. Prompts and outputs may be used to improve Meta’s products.

テキスト1.0M コンテキスト$0.10 / $0.20
Muse Spark 1.3

Muse Spark 1.3 is a multimodal reasoning model from Meta for long-running agentic, multi-agent, and coding workflows. It is designed to keep track of information across extended tasks, work through conflicting inputs, and request clarification or confirmation when needed, with an emphasis on concise execution.

テキスト1.0M コンテキスト$1.25 / $4.25
Muse Image

Muse Image is an agentic image generation model from Meta that generates and edits images from text and reference images. Unlike single-pass image models, it reasons before it renders, breaking down multi-part prompts and refining its output within the chain of thought, and invokes web search for factual accuracy on knowledge-intensive prompts.

The model supports text-to-image generation, targeted image editing, multi-image composition, reference-image conditioning for style and subject consistency across a series, and precise text rendering within generated images. Iterative editing works by passing the previous output image back with a new instruction.

画像$0.01/image
Muse Spark 1.2 Contributor

Muse Spark 1.2 contributor tier is a reasoning model from Meta designed for developers who want to start building at an even lower cost. It’s meaningfully cheaper than Muse Spark 1.2. Your prompts and outputs may be used to improve Meta’s products, making it ideal for experimentation, learning, and early-stage projects without worry about spend.

It is a reasoning model from Meta, tailored for complex agentic tasks. It accepts text, images, video, and PDF documents, returns text, and offers a 1M-token context window. The model is built to support multi-agent workflows, whether as either a main agent that plans and delegates or as a subagent executing in parallel. It works across multiple coding harnesses and supports structured output, parallel function calling, and configurable reasoning effort. In Meta’s testing, it performs well on multi-file refactors, extended debugging sessions, whole-repository generation, and tasks that stretch well past a single prompt.

テキスト1.0M コンテキスト$0.10 / $0.20
Muse Glimmer 30B

Muse Glimmer 30B is a dense, open-weight multimodal model from Meta Superintelligence Labs, distilled from Muse Spark and optimized for autonomous agents on consumer hardware. It is suited for long-horizon agentic and coding workflows, with multi-step reasoning, reliable tool use, failure recovery, image understanding, and multilingual support across more than 100 languages.

テキスト131K コンテキスト$0.30 / $1.20
Muse Spark 1.2

Muse Spark 1.2 is a reasoning model from Meta, designed for complex agentic tasks. It accepts text, images, video, and PDF documents, returns text, and offers a 1M-token context window.

The model is built to support multi-agent workflows, whether as either a main agent that plans and delegates or as a subagent executing in parallel. It works across multiple coding harnesses and supports structured output, parallel function calling, and configurable reasoning effort. In Meta’s testing, it performs well on multi-file refactors, extended debugging sessions, whole-repository generation, and tasks that stretch well past a single prompt.

テキスト1.0M コンテキスト$1.25 / $4.25
Muse Spark 1.1

Muse Spark 1.1 is a multimodal reasoning model from Meta, built for agentic tasks. It accepts text, images, video, and PDF documents and returns text, with a 1M-token context window.

The model is designed to orchestrate multi-agent workflows, acting as either a main agent that plans and delegates or as a subagent, and generalizes zero-shot to new tools, MCP servers, and custom skills. It supports structured output, parallel function calling, built-in search with citations, and configurable reasoning effort. Meta reports strong performance on real-world coding across large codebases, computer-use workflows, and visual-to-code generation.

テキスト1.0M コンテキスト$1.25 / $4.25