
Pular para o conteúdo
Alfa
  • Modelos
  • Classificações
  • Ori
Falar com vendas

Rodapé

OpenRouterOpenRouter
© 2026 OpenRouter, Inc

Produto

  • Chat
  • Classificações
  • Avaliações de desempenho
  • Aplicativos
  • Descobrir
  • Modelos
  • Ori
  • Coleções
  • Provedores
  • Ferramentas
  • Preços
  • Business
  • Enterprise
  • Laboratório

Empresa

  • Sobre
  • Blog
  • Clientes
  • Carreiras
    Vagas
  • Privacidade
  • Termos de serviço
  • Central de confiança
  • Suporte
  • Funciona com OR
  • Dados
  • Marca

Desenvolvedor

  • Documentação
  • Referência da API
  • Plataforma para desenvolvedores
  • Status
  • Mapa do site para IA

Conectar

  • Discord
  • GitHub
  • LinkedIn
  • X
  • YouTube
Favicon de qwen

Qwen: Qwen Image 2.1 Turbo

qwen/qwen-image-2.1-turbo

Avaliações de desempenhoComparar

Qwen Image 2.1 Turbo is the fast, lower-cost tier of the Qwen Image 2.1 series from Qwen, for image generation and editing where throughput and price matter more than peak fidelity. See Qwen Image 2.1 Pro for the higher-quality tier.

Modalidades
Preço
from US$ 0,0184/image
Contexto
66K
Lançado
16 de out. de 2026
Avaliações de desempenhoComparar
Área de testesAvaliações de desempenhoProvedoresPreçosDesempenhoDisponibilidadeAplicativosAtividadePerguntas frequentesExplorar

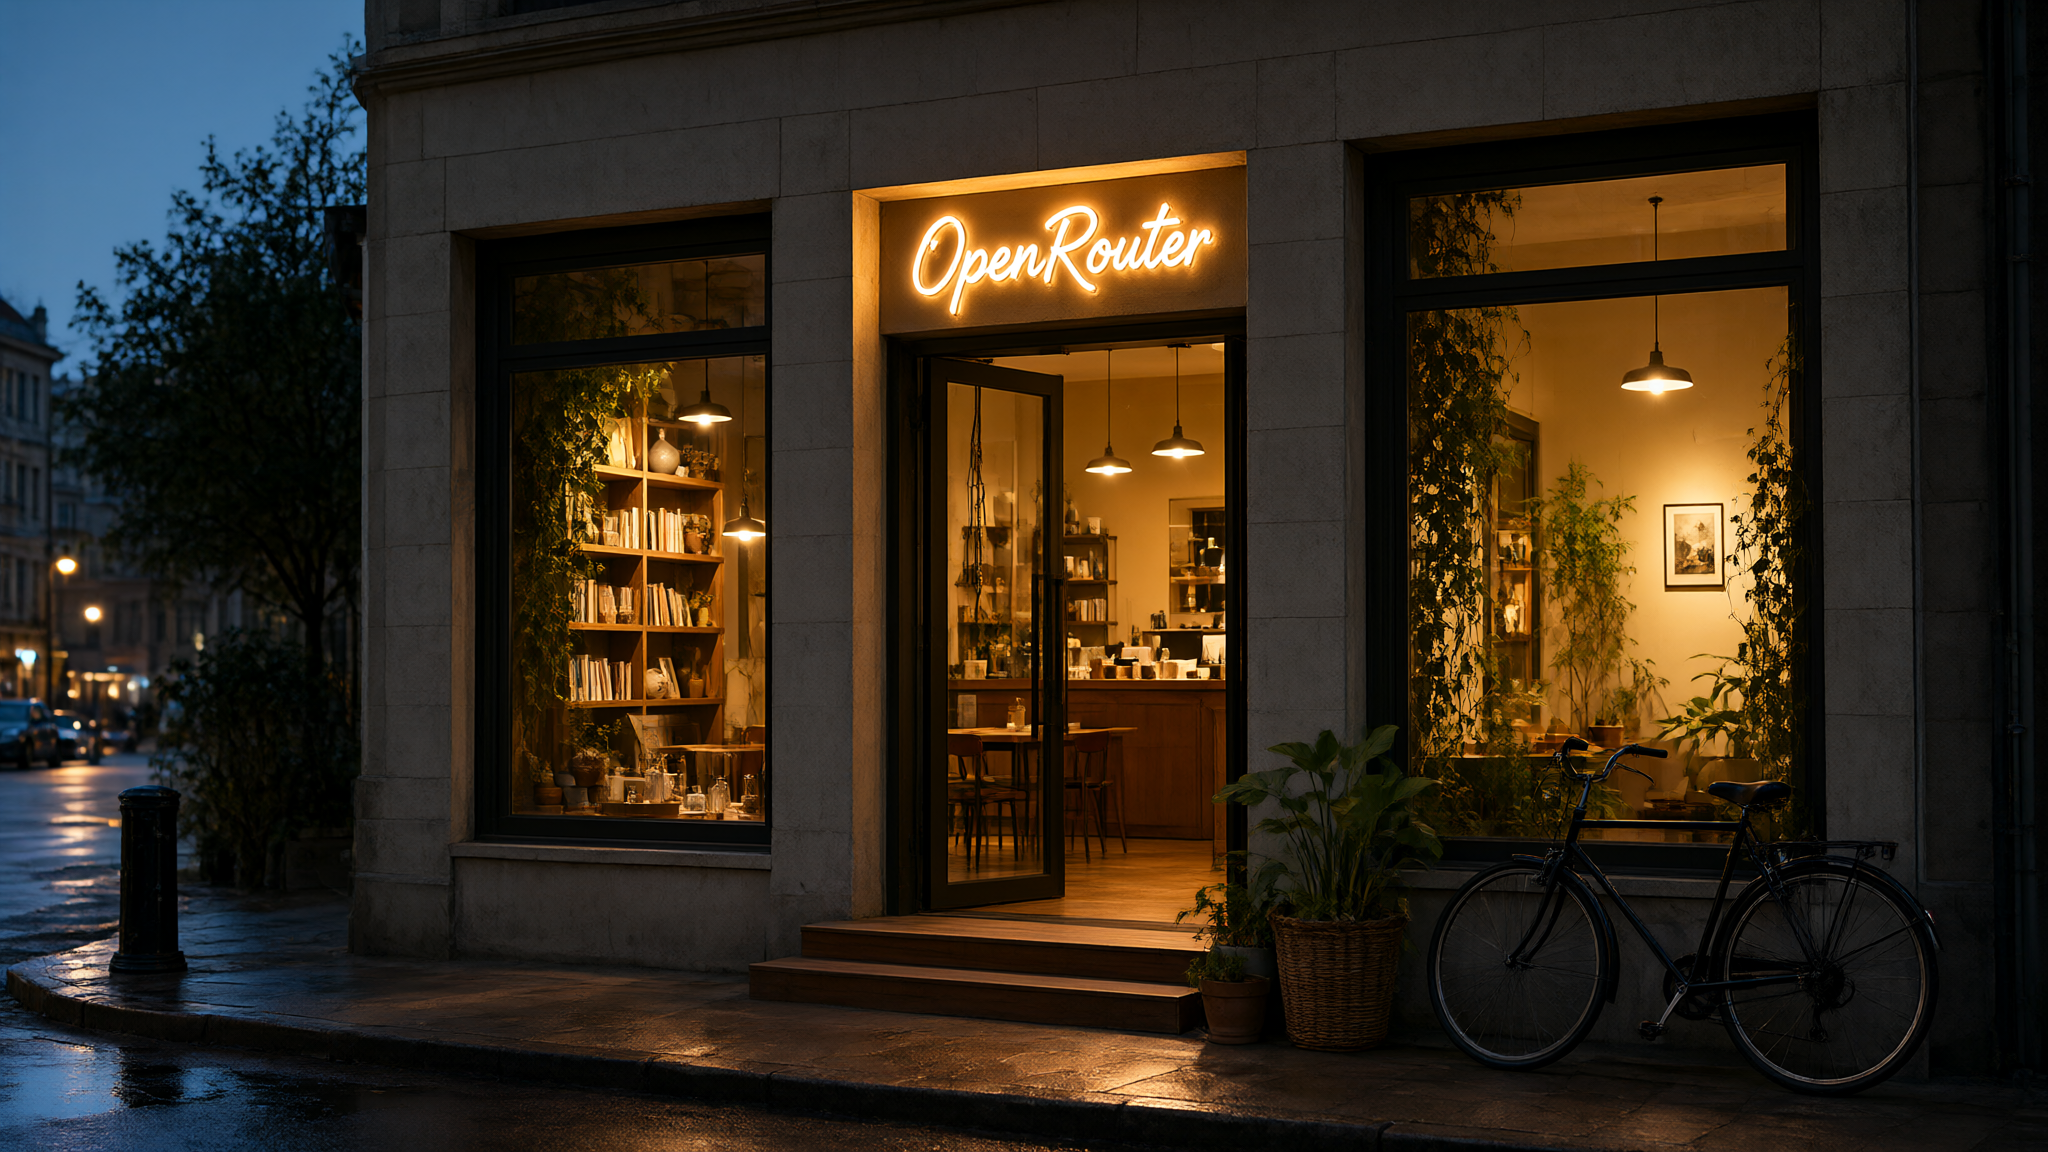
Example outputs summary for Qwen: Qwen Image 2.1 Turbo

  • Texto para imagem: Editorial architectural photograph of a contemporary neighborhood storefront at blue hour, glowing warmly against the dusk. Above the entrance, a warm-white neon sign in flowing hand-bent cursive reads exactly "OpenRouter", the only text in the scene. Large windows reveal a cozy, lived-in interior: wood shelves styled with books and ceramics, lush trailing plants, and soft pendant lighting. Potted plants and a bicycle rest by the entrance, and golden light spills across the wet pavement in gentle reflections. Straight-on composition, realistic materials, quiet street with no people. — gerado com Qwen: Qwen Image 2.1 Turbo

Área de testes

Avaliações de desempenho

Pontuações em avaliações padronizadas e as próprias saídas deste modelo para prompts compartilhados de testes de desempenho. Porcentagens maiores são melhores — e cada posição mostra onde este modelo fica entre os modelos avaliados naquela fonte.

Benchmark outputs summary for Qwen: Qwen Image 2.1 Turbo

  • Full wine glass: A wine glass filled to the brim with white wine, the surface level with the rim of the glass, standing upright on a plain wooden table. Straight-on eye-level shot, glass upright and not tilted, no other objects in the frame. (Empatado na posição 10º de 60 neste prompt)
  • Closed umbrellas: Wide street-level photograph of about twelve people crossing a city street in heavy rain. Every person is carrying a closed, furled umbrella held down at their side. Not a single umbrella is open. Each umbrella is clearly visible. They are all getting soaked. No other people in the frame. (Empatado na posição 17º de 60 neste prompt)
  • Three fingers: Close straight-on photograph of an open right hand raised palm towards the camera, with exactly three fingers extended straight up and the other two folded down into the palm. Plain background, nothing else in the frame. (Empatado na posição 1º de 60 neste prompt)
  • Cards & dice: Exactly four playing cards face up in a single straight row on a polished marble counter, evenly spaced, all the same size, showing the seven of hearts, the eight of spades, the nine of diamonds and the ten of clubs from left to right. No other objects in the frame. Straight-on eye-level shot, soft even light. (Empatado na posição 17º de 60 neste prompt)
  • Long exact string: A white A4 poster on a brick wall reading exactly "SPRING CLEARANCE - EVERYTHING 40% OFF - SATURDAY 14 JUNE, 9AM TO 6PM". No other text in the frame. (Empatado na posição 1º de 60 neste prompt)
  • Multiple languages: Straight-on photograph of a white overhead directional sign in an international airport terminal, with a black arrow pointing right at the left end. The sign carries the same word in four scripts on four stacked lines, in this order from top to bottom: "DEPARTURES", then the Japanese 出発, then the Korean 출발, then the Arabic المغادرة. Clean sans-serif lettering, sharp focus, no other text anywhere in the frame. (Empatado na posição 1º de 60 neste prompt)
  • Occlusion: Straight-on eye-level photograph of a plain wooden desk. On the left, a closed hardcover book with a dark red cover stands upright, its front cover facing the camera. A blue ceramic mug stands on the desk to the right of the book and clearly further back, about 20 cm behind it, positioned so that the right edge of the book overlaps and hides the left third of the mug. The mug's handle points to the right and the whole rim of the mug is visible. Bare desk surface is visible between the book and the mug. Nothing else on the desk. Plain wall behind, soft even light. (Empatado na posição 39º de 60 neste prompt)
  • Mirror: Straight-on eye-level photograph of a bathroom vanity. A large rectangular mirror covers the wall behind the counter and its bottom edge meets the countertop, so both the objects and their reflections are visible. On the counter, a tall red toothbrush cup on the left and a tall green glass bottle on the right, both roughly 20 cm tall and well apart from each other. The mirror reflects the counter and the objects on it accurately. Nothing else in the frame. (Empatado na posição 40º de 60 neste prompt)
  • Plain zebra: Photograph of a zebra standing side-on in short grass. Its coat is a uniform solid grey with no stripes, no bands and no markings of any kind anywhere on its body. The whole animal is visible. Sharp focus. (Empatado na posição 19º de 60 neste prompt)
  • Times Square: Wide street-level photograph of Times Square in New York at night, wet asphalt reflecting the lights. Every billboard, screen, storefront window, awning, taxi door and road marking is completely blank — lit with plain colour fields and soft gradients only. No letters, no words, no numbers, no logos, no lettering of any kind anywhere in the frame. Sharp focus, straight-on shot. (Empatado na posição 11º de 60 neste prompt)
  • Minimal diff: From the reference photo, change only the sign text to "ROUTE 7 ESPRESSO - OPEN TILL 8". Keep the sign, wall, lighting and framing identical. (Empatado na posição 5º de 60 neste prompt)
  • Object removal: Remove only the second cup from the left in the reference photo. Leave the other four cups exactly as they are, in the same positions, and leave the shelf, towel, wall, plant and lighting untouched. (Empatado na posição 1º de 60 neste prompt)
  • Person removal: In the reference photo, remove only the person in the yellow coat. Their shadow on the pavement and their reflection in the shop window must be removed as well. Reconstruct the pavement and the window glass behind them. The person in the red coat and the person in the green coat must stay completely unchanged, including their own shadows and their own reflections. Change nothing else in the frame. (Empatado na posição 31º de 60 neste prompt)
  • Product placement: Product photograph of the ceramic mug from the reference image, standing upright on a café table. Show the same side of the mug, from the same side-on eye-level angle as the reference, with the handle on the right. The shape, proportions, colours, moulded relief and every painted detail must match the reference exactly. Only the setting and lighting change: soft daylight in a café interior, shallow depth of field. (Empatado na posição 1º de 60 neste prompt)
  • Four references: Place the person from the portrait reference at the desk in the scene reference, wearing the rust orange canvas jacket from its reference and holding the navy blue travel mug from its reference in one hand. Keep the face, the jacket and the mug exactly as they appear in the references — same colours, same details, same proportions. Do not change the room. (Empatado na posição 14º de 60 neste prompt)
  • Portraits: Studio headshot of a woman in a charcoal blazer against a mid-grey seamless backdrop, lit by a large softbox slightly above and to the left with a soft fill from the right, catchlights in both eyes. An 85mm look with shallow depth of field, skin texture and flyaway hairs kept rather than smoothed.
  • People in scenes: Photograph of four cooks working the pass in a restaurant kitchen at service, plating three dishes at once, several hands in frame and some of them overlapping. One cook partly hidden behind another, steam rising into hard overhead light, each face clearly a different person.
  • Animals: Photograph of a tabby cat asleep on a sunlit windowsill, fur lit from behind so the individual hairs glow at the edges, one ear turned toward the camera. Shallow depth of field, a houseplant soft in the background, quiet morning light.
  • Landscape and nature: Photograph of an old-growth temperate rainforest after rain, moss on every trunk and fallen log, ferns dense across the floor, thin fog between the far trees. Overcast light with no direct sun, everything from the nearest fern to the last trunk in focus.

Provedores

Este modelo é hospedado por um provedor. O OpenRouter encaminha todas as solicitações diretamente a ele — não há decisões de roteamento a tomar.

Preços

O preço médio que os clientes realmente pagam por este modelo, ao lado dos preços publicados pelos provedores. O cache e os descontos fazem com que o preço efetivamente pago seja frequentemente bem inferior ao preço anunciado.

Desempenho

A vazão indica a velocidade com que o modelo escreve (tokens por segundo — quanto maior, melhor). A latência é o tempo total de ida e volta (quanto menor, melhor). TTFT é o tempo até o primeiro token — quanto tempo leva para você ver algo aparecer (quanto menor, melhor).

Disponibilidade

A disponibilidade é a porcentagem dos últimos 3 dias em que pelo menos um provedor estava respondendo às solicitações. A disponibilidade é a porcentagem de tempo em que a inferência foi realizada com sucesso. O OpenRouter monitora continuamente e usa o próximo melhor provedor quando um deles retorna um erro.

Aplicativos

Aplicativos públicos que enviam mais tráfego para este modelo. Um bom indicador de como são as cargas de trabalho reais em produção — e uma pista sobre os casos de uso para os quais este modelo é mais adequado.

Atividade

Volume de tokens e tráfego de requisições para este modelo ao longo do tempo.

API

Código pronto para chamar este modelo. A API do OpenRouter é compatível com a OpenAI — a maioria dos SDKs funciona apenas trocando a URL base. A única coisa que muda entre os modelos é o slug do modelo abaixo.

Atualmente indisponível por meio do roteamento intrarregional da UE. Documentação de roteamento na região

Explorar mais modelos

Modelos de IA com visão: LLMs multimodais para compreensão de imagensColeçãoModelos de geração de imagensColeçãoClassificação de modelos de imagemClassificação
Latência de ponta a ponta
GratuitoUS$ 0,018413,37s
100,00%
Latência de ponta a ponta
13,37s

P50, melhor provedor

Disponibilidade (3d)O modelo estava acessível. Requisição roteada para um provedor.
100,00%
Disponibilidade (3d)O modelo retornou inferência de qualquer provedor. Erros e respostas vazias contam negativamente para essa métrica.
99,89%

Disponibilidade nos últimos 3 dias

Últimas 72 horas
Disponibilidade 99,89%
Há 3 diasHá 2 diasOntemAgora

Disponibilidade nas últimas 24 horas

OpenRouter Availability
99,88%

Quando ocorre um erro em um provedor upstream, podemos nos recuperar roteando para outro provedor saudável, se os filtros da sua solicitação permitirem. Você pode acessar os dados de disponibilidade por provedor de forma programática pela API de endpoints. Saiba mais sobre nossas opções de balanceamento de carga e roteamento de provedores.

1.
Favicon de https://oceanapi.dev/
OceanAPI
novo
5,61Mtokens
2.
Favicon de https://www.henhideaways.com/
Hen Hideaways Social
novo
5,33Mtokens
3.
Favicon de https://caravansanat.com/
content-engine
novo
5,21Mtokens
4.
Favicon de https://github.com/local/AI_video_zavod
Kurpatov Video Zavod
novo
3,04Mtokens
5.
Favicon de https://clash-of-light.local/
Clash of Light atelier
novo
1,6Mtokens

Perguntas frequentes

Qwen Image 2.1 Turbo is the fast, lower-cost tier of the Qwen Image 2.1 series from Qwen, for image generation and editing where throughput and price matter more than peak fidelity. See Qwen Image 2.1 Pro for the higher-quality tier.

Qwen Image 2.1 Turbo custa US$ 0,0184/image no plano 1K.

Qwen Image 2.1 Turbo renderiza em 1K e 2K, oferece suporte às proporções de imagem 1:1, 1:2, 1:4, 2:1, 2:3, 3:2 e mais 7 e pode gerar até 6 imagens por solicitação.

Qwen Image 2.1 Turbo aceita texto e imagens como entrada e retorna imagens. Até 4 imagens de referência podem ser anexadas a uma solicitação de edição de imagens.

Qwen Image 2.1 Pro, Qwen Image 3 Pro e Qwen Image 3 são outros modelos de imagem de Qwen.

Qwen Image 2.1 Turbo foi lançado em 16 de outubro de 2026.

Mais modelos de Qwen

Qwen Image 2.1 Turbo

Qwen Image 2.1 Turbo is the fast, lower-cost tier of the Qwen Image 2.1 series from Qwen, for image generation and editing where throughput and price matter more than peak fidelity. See Qwen Image 2.1 Pro for the higher-quality tier.

Imagemfrom US$ 0,0184/image
Qwen Image 2.1 Pro

Qwen Image 2.1 Pro is an image generation and editing model from Qwen, the higher-quality tier of the Qwen Image 2.1 series. Choose it over Qwen Image 2.1 Turbo when output fidelity matters more than cost or speed.

Imagemfrom US$ 0,046/image
Qwen3.8 Max Prime

Qwen3.8 Max Prime is a higher-throughput variant of Qwen3.8 Max from Alibaba's Qwen team, served as a separate SKU at a higher price point. It accepts text, image, and video input and returns text, with a 1M-token context window and reasoning enabled by default. Tool calling, structured outputs, and configurable reasoning effort are supported, matching Qwen3.8 Max.

TextoContexto de 1MUS$ 4 / US$ 12
Qwen3.8 Omni Flash

Qwen3.8 Omni Flash is an omni-modal reasoning model from Alibaba, the first Qwen model built around agentic capabilities with native audio-video understanding. It is suited for audio-video analysis and summarization, video editing and production workflows, audio-video dialogue, coding, knowledge work, and GUI interaction, and it is particularly strong at long-form multimedia tasks that combine speech, sound, and visual context. It also supports two-channel and four-channel spatial audio understanding.

TextoContexto de 1MUS$ 0,15 / US$ 0,47
Qwen3.8 Max

Qwen3.8 Max 0902 is an updated snapshot of Qwen3.8 Max from Alibaba's Qwen team. It is a 2.4-trillion-parameter mixture-of-experts model that accepts text, image, and video input and returns text, with a 1M-token context window and reasoning enabled by default.

This snapshot is post-trained for coding and agentic work, including multi-step software projects, multi-tool orchestration, and long-horizon task execution. It also targets chart reasoning, document parsing, and multimodal understanding over long documents and extended video. Tool calling, structured outputs, and configurable reasoning effort are supported.

TextoContexto de 1MUS$ 2 / US$ 6
Qwen3.8 Flash

Qwen3.8 Flash is a multimodal reasoning model from Alibaba. It is suited for coding assistance, agentic workflows, visual understanding, document and codebase analysis, desktop interaction, chart analysis, and long-video analysis.

TextoContexto de 1MUS$ 0,15 / US$ 0,47
Qwen3 Reranker 0.6B

Qwen3 Reranker 0.6B is the smallest text reranking model from Alibaba Cloud in the Qwen3 Reranker series. Built on the Qwen3 architecture, it evaluates query-document pairs to produce relevance scores for retrieval and RAG pipelines. Supports 100+ languages with instruction-aware reranking. Designed for low-latency, resource-constrained deployments.

Reclassificação
Qwen3 Reranker 4B

Qwen3 Reranker 4B is a text reranking model from Alibaba Cloud built on the Qwen3 architecture. It evaluates query-document pairs to produce relevance scores for use in retrieval and RAG pipelines. Supports 100+ languages and programming languages, with instruction-aware reranking that allows customizing scoring criteria per task. A compact 4B alternative balancing performance and inference cost.

Reclassificação
Qwen3.8 27B

Qwen3.8 27B is an open-weight dense vision-language model from Qwen. It is suited for coding, professional workflows, research, multimodal interaction, and long-running agent tasks, with flexible thinking that can be enabled or disabled.

TextoContexto de 1,0MUS$ 0,005 / US$ 0,284
Qwen3 Reranker 8B

Qwen3 Reranker 8B is a text reranking model from Alibaba Cloud built on the Qwen3 architecture. It evaluates query-document pairs to produce relevance scores for use in retrieval and RAG pipelines. Supports 100+ languages and programming languages, with instruction-aware reranking that allows customizing scoring criteria per task. Offers strong performance on multilingual benchmarks including MTEB, CMTEB, and MMTEB.

ReclassificaçãoUS$ 0,20/M tokens
Qwen3 ASR 1.7B

Qwen3 ASR 1.7B is an automatic speech recognition model from Qwen. It supports multilingual language identification and transcription across 30 languages and 22 Chinese dialects, with streaming and offline inference plus segment-level and word-level timestamps.

TranscriçãoUS$ 0,000008/second
Qwen3 ASR 0.6B

Qwen3 ASR 0.6B is a compact automatic speech recognition model from Qwen. It supports multilingual language identification and transcription across 30 languages and 22 Chinese dialects, with streaming and offline inference plus segment-level and word-level timestamps.

TranscriçãoUS$ 0,000003/second
Qwen3.8 2.4T A95B

Qwen3.8 2.4T A95B is an open-weight sparse mixture-of-experts model from Qwen and the open-weight variant of Qwen3.8 Max, with 95 billion active parameters out of 2.4 trillion total. It is suited for coding, research, complex reasoning, and agentic workflows.

TextoContexto de 1,0MUS$ 2 / US$ 6
Qwen Image 3 Pro

Qwen Image 3 Pro is an image generation and editing model from Qwen. It supports precise rendering of text and details as small as 10px, along with richer world knowledge compared to previous generations.

Imagemfrom US$ 0,04/image
Qwen Image 3

Qwen Image 3 is a unified image generation and editing model from Qwen. It supports precise rendering of text and details as small as 10px, along with a richer world knowledge base than previous generations.

Imagemfrom US$ 0,03/image
Qwen3.8 Max

Qwen3.8 Max (0803) is the August 3, 2026 checkpoint of Qwen3.8 Max, the flagship model in Alibaba's Qwen3.8 series and the general-availability successor to the Qwen3.8 Max Preview. It is a multimodal reasoning model intended for complex reasoning, visual understanding, coding, and agentic workflows. This checkpoint was superseded by Qwen3.8 Max (0902) on September 5, 2026.

TextoContexto de 1M
Qwen3.7 Flash

Qwen3.7 Flash is a vision-language reasoning model from Alibaba. It is suited for multimodal agents, visual coding, search, and computer interaction, with strengths in object recognition, spatial understanding, and real-world visual perception.

TextoContexto de 1MUS$ 0,03 / US$ 0,13
Qwen-Audio-3.0-TTS Flash

Qwen-Audio-3.0-TTS Flash is Alibaba's fast, cost-efficient text-to-speech model, generating spoken audio from text via the DashScope Speech Synthesizer API.

FalaUS$ 15/M characters
Qwen-Audio-3.0-TTS Plus

Qwen-Audio-3.0-TTS Plus is Alibaba's higher-quality text-to-speech model, generating spoken audio from text via the DashScope Speech Synthesizer API.

FalaUS$ 20/M characters
Qwen3.7 Plus

Qwen3.7-Plus is a cost-effective model in Alibaba's Qwen3.7 series. It supports text and image input with text output, building on the series' text capabilities with a comprehensive upgrade to its vision-language abilities while retaining full-stack, agent-level intelligence for coding, tool use, and productivity workflows. Its distinguishing trait is multi-modal interactive hybrid agent capability: it can perceive real-world scenes, read screens and interact with GUIs, generate code from visual references, and perform end-to-end navigation within mobile apps.

TextoContexto de 1MUS$ 0,32 / US$ 1,28