跳转到内容
Alpha
  • 模型
  • 排行榜
  • Ori
联系销售

页脚

OpenRouterOpenRouter
© 2026 OpenRouter, Inc

产品

  • 聊天
  • 排行榜
  • 基准测试
  • 应用
  • 发现
  • 模型
  • Ori
  • 合集
  • 提供商
  • 工具
  • 定价
  • Business
  • Enterprise
  • 实验室

公司

  • 关于
  • 博客
  • 客户
  • 招聘
    招聘
  • 隐私
  • 服务条款
  • 信任中心
  • 支持
  • 兼容 OR
  • 数据
  • 品牌

开发者

  • 文档
  • API 参考
  • 开发者平台
  • 状态
  • AI 站点地图

连接

  • Discord
  • GitHub
  • LinkedIn
  • X
  • YouTube
inclusionai 的网站图标

inclusionAI: Ming Image 0.1 Design

inclusionai/ming-image-0.1-design

模型权重
基准测试

Ming Image 0.1 Design is a text-to-image model from inclusionAI aimed at graphic-design output, with an emphasis on legible text rendering inside the generated image. It generates from a prompt only and does not accept reference images. Output format can be requested as PNG, JPEG, or WebP. Image dimensions are chosen by the model rather than by the request, so explicit sizes and aspect ratios are rejected instead of silently reshaped.

模态
上下文
33K
发布时间
2026年9月22日
基准测试
试验场活动常见问题探索

Example outputs summary for inclusionAI: Ming Image 0.1 Design

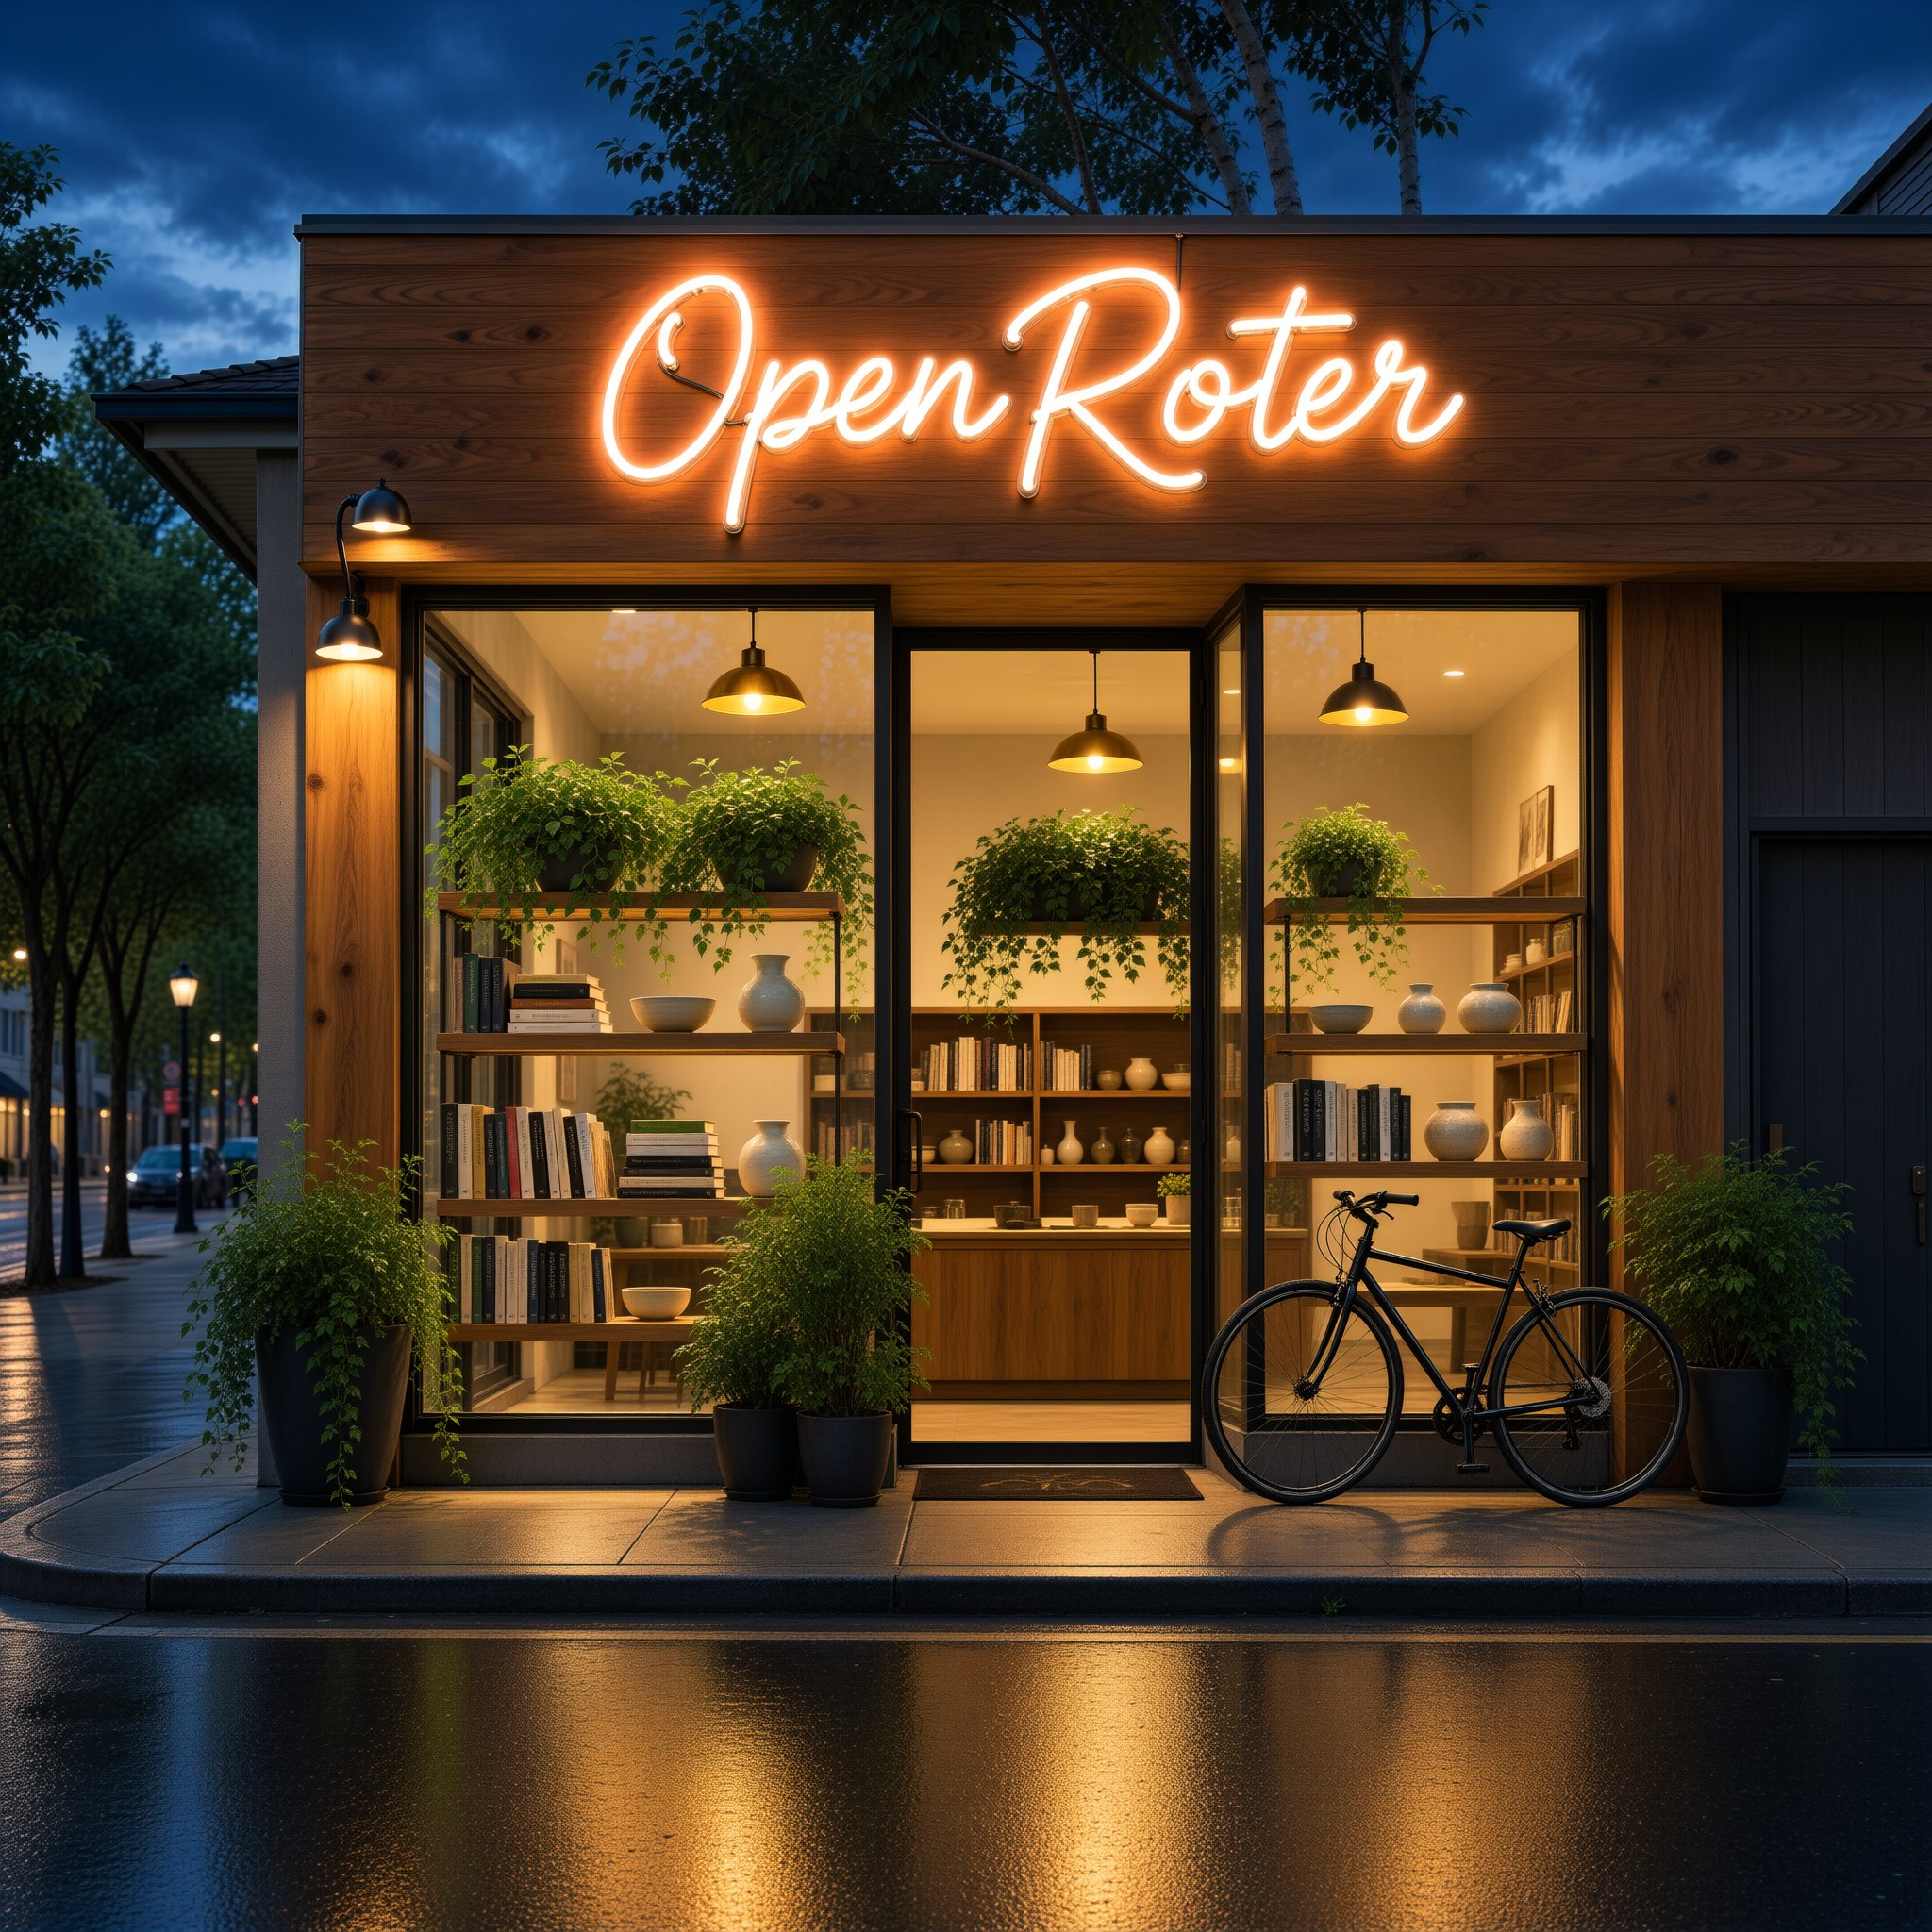
  • 文生图: Editorial architectural photograph of a contemporary neighborhood storefront at blue hour, glowing warmly against the dusk. Above the entrance, a warm-white neon sign in flowing hand-bent cursive reads exactly "OpenRouter", the only text in the scene. Large windows reveal a cozy, lived-in interior: wood shelves styled with books and ceramics, lush trailing plants, and soft pendant lighting. Potted plants and a bicycle rest by the entrance, and golden light spills across the wet pavement in gentle reflections. Straight-on composition, realistic materials, quiet street with no people. — 使用 inclusionAI: Ming Image 0.1 Design 生成

试验场

活动

此模型的 token 用量和请求流量随时间的变化。

目前无法通过 EU 区域内路由使用。 区域内路由文档

探索更多模型

图像生成模型集合图像模型排行榜排名

常见问题

Ming Image 0.1 Design is a text-to-image model from inclusionAI aimed at graphic-design output, with an emphasis on legible text rendering inside the generated image. It generates from a prompt only and does not accept reference images. Output format can be requested as PNG, JPEG, or WebP.

Ming Image 0.1 Design 接受 文本 作为输入,并返回 图像。

Ming Image 0.1 Design 于 2026年9月22日 发布。

更多模型,来自 inclusionai

Ling 3.1 Flash

Ling 3.1 Flash is a hybrid reasoning mixture-of-experts model from inclusionAI, with 25B active parameters out of 560B total.

文本1M 上下文US$0.075 / US$0.225
Ming Image 0.1 Design Layer

Ming Image 0.1 Design Layer is an image-to-image model from inclusionAI that decomposes a flattened design image into separate RGBA layers, such as a background layer and foreground elements, and returns one image per layer. It requires exactly one reference image and a prompt describing the layer plan. Output format can be requested as PNG or WebP. Output dimensions follow the input image, so explicit sizes and aspect ratios are rejected instead of silently reshaped.

图像
Ling 3.0 Flash VL

Ling 3.0 Flash VL builds on Ling 3.0 Flash (124B total / 5.5B active MoE from InclusionAI), further strengthening its language capabilities while adding native visual perception and advanced visual agent capabilities. Hybrid instant/reasoning model with tool calling.

文本131K 上下文US$0.06 / US$0.18
Ling 3.0 Flash Sante

Ling 3.0 Flash Sante is a health and medicine-focused mixture-of-experts model from InclusionAI, built on Ling 3.0 Flash with 5.1B active parameters out of 124B total. It is designed for medical knowledge reasoning, clinical safety, evidence-based retrieval, and long-horizon medical tasks, while retaining general capabilities in reasoning, coding, and agentic tasks.

文本262K 上下文
Ling 3.0 Flash Fin

Ling 3.0 Flash Fin is a finance-focused mixture-of-experts model from InclusionAI, built on Ling 3.0 Flash with 5.1B active parameters out of 124B total. It is designed for real-world investment workflows that require complex multi-step tasks and long-horizon planning and execution, while retaining general capabilities in reasoning, coding, and mathematics.

文本262K 上下文
Ling 3.0 Tiny

Ling 3.0 Tiny is a mixture-of-experts model from InclusionAI, with 1.3B active parameters out of 7.9B total. It is designed for responsive agents, instruction following, and multi-turn conversations, with switchable thinking and instant modes.

文本262K 上下文
Ling 3.0 Flash

Ling-3.0-flash is a 124B-parameter Mixture-of-Experts (MoE) model, with approximately 5.1B parameters activated per token.

The model is designed with token efficiency and production-scale agentic inference as key priorities, enabling developers to complete more useful work within constrained token, latency, and serving-cost budgets.

文本262K 上下文US$0.021 / US$0.063
Ring-2.6-1T

Ring-2.6-1T is a 1T-parameter-scale thinking model with 63B active parameters, built for real-world agent workflows that require both strong capability and operational efficiency. It is optimized for coding agents, tool use, and long-horizon task execution, delivering leading results on benchmarks including PinchBench, ClawEval, TAU2-Bench, and GAIA2-search.

With adaptive reasoning effort across high and xhigh modes, Ring-2.6-1T dynamically allocates reasoning budget based on task complexity. This enables stronger performance with lower token overhead, especially in tool-heavy and multi-turn agent workflows.

Ring-2.6-1T is designed for advanced coding agents, complex reasoning pipelines, and large-scale autonomous systems where execution quality, latency, and cost efficiency all matter.

文本262K 上下文
Ling-2.6-1T

Ling-2.6-1T is an instant (instruct) model from inclusionAI and the company’s trillion-parameter flagship, designed for real-world agents that require fast execution and high efficiency at scale. It uses a “fast thinking” approach to reduce costs to roughly a quarter of comparable models while maintaining top-tier performance.

The model achieves state-of-the-art results on benchmarks such as AIME26 and SWE-bench Verified, and is well suited for advanced coding, complex reasoning, and large-scale agent workflows where both capability and efficiency are critical.

文本262K 上下文
Ling-2.6-flash

Ling-2.6-flash is an instant (instruct) model from inclusionAI with 104B total parameters and 7.4B active parameters, designed for real-world agents that require fast responses, strong execution, and high token efficiency. It delivers performance comparable to state-of-the-art models at a similar scale while significantly reducing token usage across coding, document processing, and lightweight agent workflows.

文本262K 上下文